
Avo AI
Avo AI puts a chat bar on every page of your Avo app, so the people on your team can ask about your data in their own words and get an answer instead of filing a ticket. AI in your Avo app compares it with the MCP server. It sees only what that person's policies allow, updates and deletes wait until someone clicks Confirm, and every write lands in an audit log.
Under the hood it is a set of tools the assistant uses to query, create, update, and delete records, and admin resources for browsing chats, messages, tool calls, and models.
New here, or wondering what to type into it? What you can ask is the catalog of everything the assistant does, with a sample prompt for each.
WARNING
The feature and docs are both work in progress.
Requirements
- Avo 4
- An API key for an LLM provider supported by RubyLLM (OpenAI, Anthropic, Gemini, and others)
- RubyLLM 2.1 or newer within the 2.x line, installed for you as a dependency.
- PostgreSQL
Installation
1. Install the gem
Add the gem to your application's Gemfile:
gem "avo-ai", source: "https://packager.dev/avo-hq/"Then run:
bundle install2. Run the installer
bin/rails generate avo:ai install
bin/rails db:migrate
This creates the avo_ai_* tables — plus RubyLLM's internal ruby_llm_* tables (model registry, tool calls, usage ledger, batches, MCP credentials), unless the app already has them — and writes config/initializers/ruby_llm.rb (skipped if it already exists). It also appends every AI setting — commented out, at its default — to the end of config/initializers/avo.rb, so the options are in the file waiting to be uncommented rather than in terminal output that scrolls away. If the file already configures config.ai, it's left untouched.
3. Set your provider API key
The generated config/initializers/ruby_llm.rb reads OPENAI_API_KEY by default.
RubyLLM.configure do |config|
  config.openai_api_key = ENV.fetch("OPENAI_API_KEY", nil)
  # config.anthropic_api_key = ENV.fetch("ANTHROPIC_API_KEY", nil)
  # config.gemini_api_key = ENV.fetch("GEMINI_API_KEY", nil)
end
Store the key in your environment or Rails.application.credentials — never hardcode it in the initializer.
Then load RubyLLM's model registry, and re-run it periodically (or call RubyLLM.models.refresh) to keep model labels and pricing current:
bin/rails ruby_llm:load_modelsLater refreshes don't need the terminal: the Models resource (added to the menu below) ships a standalone Refresh models action that pulls the published catalog plus the latest models from every configured provider. There's nothing to restart after a refresh — a background job that meets a model its process doesn't know yet re-reads the registry and retries on its own.
4. Add the admin resources to the menu
In config/initializers/avo.rb, inside the config.main_menu block:
section "AI", icon: "heroicons/outline/sparkles" do
  resource "avo_ai/chats"
  resource "avo_ai/messages"
  resource "avo_ai/models"
  resource "avo_ai/skills"
end
The resources and controllers ship inside the gem — there's nothing to generate into your app.
5. Verify
bin/rails runner "puts Avo::Ai::Chat.count"Expect 0 and no error. Restart your server and the chat bar appears on every Avo page, with an AI section in the sidebar.
6. Teach the assistant your app
Don't skip this one. The assistant now knows Avo, not your application — what a "customer" is here, which resource an "order" lives in, the questions your team actually asks — and until you write that down it guesses, and guesses wrong. It goes in a prompt file of its own, and the gem ships a flow that writes it with you. The install isn't finished until you've followed Teach the assistant your app.
Configuration
Avo AI registers its settings on Avo's own configuration, so everything lives in config/initializers/avo.rb under the ai namespace:
Avo.configure do |config|
  # Reasoning effort for thinking-capable models ("low", "medium", "high").
  # Only sent to models that support reasoning; ignored otherwise.
  config.ai.thinking_effort = "medium"

  # Token budget for the model's thinking trace (positive integer, min 1024).
  config.ai.thinking_budget = 2048
  # Set both — see "Thinking" below. A model takes one knob or the other.

  # Clock format for chat timestamps: :auto (default), :h12, or :h24.
  config.ai.time_format = :h24

  # What a download from a URL may cost (see "Getting new files in").
  # Set only the keys you want to change; the rest keep their defaults.
  config.ai.remote_file = {
    max_size: 25.megabytes, # ceiling on the downloaded file
    open_timeout: 5,        # seconds to connect
    read_timeout: 10,       # seconds per read
    deadline: 30,           # seconds for the whole download
    max_redirects: 3
  }

  # What reading a file through the chat may cost, and how big one import may be
  # (see "Reading files and importing from them"). Set only the keys you want to change.
  config.ai.files = {
    max_read_size: 10.megabytes, # ceiling on a file read_file will decode
    max_slice: 500,              # lines or rows one read_file call may return
    max_slice_bytes: 256.kilobytes, # bytes one read_file call may return, whatever the line count
    max_import_rows: 1000        # data rows one confirmed import may create
  }

  # What the composer lets people upload (see "Send files with a message"). Set only the keys
  # you want to change. accept takes what an HTML accept attribute does: MIME types, wildcards
  # ("image/*", or "*/*" for anything) and extensions (".csv").
  config.ai.uploads = {
    max_size: 25.megabytes,
    accept: %w[image/png image/jpeg image/gif image/webp application/pdf text/* application/json
      .md .markdown .txt .csv .tsv .json]
  }

  # Records one batch update may change (see "Reading files and importing from them"). 1 to 500.
  config.ai.max_update_records = 50

  # Which tools the assistant gets (see "Choose which tools the assistant gets").
  config.ai.excluded_tools = [:delete_record]
  config.ai.extra_tools = ["CrmTool"]

  # Suggestion chips a brand-new chat offers before the first message. Unset (the default) shows
  # generic suggestions, translatable through i18n (avo.ai.empty_state.suggestions). Set this to
  # replace them outright with your own, e.g. naming real resources.
  config.ai.empty_state_suggestions = ["Show me this week's orders", "Create a new customer"]

  # Close chat-bar pills nobody has opened for this long (see "Closing idle tabs automatically").
  # Unset (the default), nil, or false keeps them until closed.
  config.ai.tab_expiry = 30.days

  # Let people connect remote MCP servers from the chat (see "Turn on MCP connections").
  # Off by default. Needs Active Record encryption keys and the installer's migrations.
  config.ai.connectors_enabled = true
end
The two thinking options fall back to an environment variable when unset, so you can configure them through the environment instead:
| Option | Environment variable | Default |
|---|---|---|
thinking_effort | AVO_AI_THINKING_EFFORT | unset |
thinking_budget | AVO_AI_THINKING_BUDGET | unset |
When both are unset, no effort or budget is sent. Models that return their reasoning only as a summary (OpenAI and Azure reasoning models, and Anthropic's effort-only models) are still asked for that summary, so readers see a trace either way.
Thinking
Set both options. They are not alternatives, and they are not a fallback pair — they are two different knobs, and each model accepts exactly one of them. Its provider rejects the other outright.
This is not an Anthropic quirk — the split runs across providers, and which knob a model takes is a property of the model, not of the company that made it:
| Knob | Models that take it |
|---|---|
thinking_budget | claude-haiku-4-5, claude-sonnet-4-6, Gemini 2.5 |
thinking_effort | claude-opus-5, Gemini 3, OpenAI reasoning models (gpt-5, …) |
Avo reads the answer from the model's own registry entry and sends only that knob, preferring the budget where a model takes both. So a picker offering Haiku and Opus needs both values set — configure only thinking_effort and every Haiku conversation quietly answers with no thinking at all, with nothing in the logs to say so.
Both options reach every provider RubyLLM supports thinking for, which is most of them: Anthropic, OpenAI, Gemini, VertexAI, Bedrock, Azure, Mistral, Perplexity, OpenRouter, Ollama, and GPUStack. A few of those don't take direction — Mistral's Magistral models always think and ignore what you send, and local Ollama or GPUStack models get the values passed through untranslated. For the current per-provider picture, RubyLLM documents it at rubyllm.com/thinking.
Effort is passed to the provider exactly as written, so the accepted strings are the provider's, not Avo's. "low", "medium", and "high" are understood everywhere effort applies; OpenAI also takes "minimal", Gemini 3 takes only "low" and "high", and "none" turns thinking off on Anthropic. A value the provider doesn't recognise fails on the first request, not at boot. Budgets are thinking tokens, minimum 1024 on Anthropic; zero or negative reads as unset.
The same two knobs are how you size the reasoning readers see above a reply: a bigger budget or a higher effort buys a longer, deeper trace; a smaller one keeps it to a line or two. On budget models the trace is the model's own reasoning verbatim, so the budget bounds it directly. On effort models what renders is the provider's summary of the reasoning — its length loosely follows the effort, and its wording isn't steerable from your side.
A reply only gets a reasoning panel when the provider sent readable text. A bare signature or a thinking token count, which is what comes back when a model thought too briefly to summarize, shows nothing.
INFO
Thinking only reaches models that declare reasoning support. Sending it to a plain chat model like gpt-4o-mini would have the provider reject the whole request, so Avo doesn't.
Timestamps
Every timestamp in a conversation is written by the browser, not the server: message stamps and day dividers ("Today 1:43 PM") render in the reader's own timezone, and the day dividers group by the reader's calendar. A conversation is stamped the same whether it's read from Bucharest or Denver, and no timezone configuration is involved.
time_format decides only whether the clock is 12- or 24-hour — the timezone is always the reader's own:
| Value | Clock |
|---|---|
:auto | Default. Each reader's browser locale decides — an en-GB reader sees 21:42, an en-US one 09:42 PM. |
:h12 | 09:42 PM for everyone. |
:h24 | 21:42 for everyone. |
Leave it on :auto unless the admin should read the same for everyone regardless of who's signed in.
"Today" and "Yesterday" are plain translations under avo.ai.messages.today / .yesterday.
How the assistant works
Every message you send starts a fresh turn against the provider, built from three things: a system prompt, the conversation so far, and a set of tools. The model can't see your database — it only ever learns about your data by calling a tool and reading what comes back.
The system prompt is rebuilt on every turn. It's assembled from the ERB files under app/prompts/, so it always reflects the current date, the signed-in user, what the chat was started from, and any instructions you've added. Nothing about your schema is baked in ahead of time.
It works from your real schema, not a guess at it. Every query, write, and action result carries the resource's real columns, model scopes, and required attributes back to the assistant — so it builds what comes next from your names. This is done by the tools, not merely requested in the prompt: it arrives with the answer rather than being asked for first, which is why a question rarely spends a round trip on structure, and why the assistant uses your scopes — cancelled, published — instead of guessing at column filters. A query that gets a column wrong comes back with the real ones attached, so the retry is built from names too.
Reading. Query results are paginated, and "how many" goes to count_records, which returns the number and never a row — so a capped result set doesn't become a wrong number, and a count sends no record to the model provider. Any record the assistant names in its answer is rendered as a chip in the sentence itself — see Record chips.
Images load only from your app. An image in an answer loads when its address is a path on your app, a data: image, or a URL on the host set in Rails.application.routes.default_url_options. Any other image renders as a link naming its host, so an image address written into a record, a document, or a connected server's reply can't make the reader's browser send a request to that host. If default_url_options has no host, full URLs to your own app render as links too.
Writing. Updates and deletes show you a card describing the change and run only when you confirm it; the confirmation applies the change, not the model. A delete works one record at a time; an update works on one record or on many, and a batch is one card covering the whole set. Creates apply immediately, since there's nothing to preview for a record that doesn't exist yet, and creating is the one write it will repeat: "add 15 cities" creates fifteen without stopping between them. The exception is an import from a CSV, which is proposed as one card and creates its rows only when you confirm. Every executed write is recorded in an audit log, and the assistant can undo one through the same confirmation card.
Writes go through your fields. A create or update is saved the way the edit form saves it, so each field's save rules run: update_using, a belongs_to found through its resource's own finder and attach scope (a slug resolves), a key-value field's locks. The assistant writes the names the form takes — a field's id, or the param the form submits (user_id, a polymorphic field's commentable_type and commentable_id together). A column a field writes under another name (tag_list, price_cents) is refused, never silently dropped. Undo is the exception: it puts back the stored copy of the row.
Confirming a card — click or type. Every card that waits on you — an update, a delete, an undo, an action run, an attach-by-URL, an import — settles the same two ways: click its button (Confirm, or Run on an action, Attach on a file), or just tell the assistant to go ahead in the composer — "do it", "go for it", "run it", "commit", "apply it", "yes". A typed confirmation is your word, so it counts exactly as the click does; the assistant still can't confirm on its own, and it can't talk its way past a Cancel. The two read differently in the transcript: a click settles the card where it sits, while what you typed is saved as your message, the card above it settles reading Confirmed, and the outcome arrives as a new card under your words. Either way, the card reads Working… while the write runs and its buttons come off, so a slow action can't look like nothing happened and get confirmed a second time. It only reads as a confirmation when that's all you say — "run it, but change the reason to budget cut" carries a fresh instruction, so the assistant re-proposes with your change instead of running the old card. An answer sent from a question card is never a confirmation either, however it reads — see Answering the assistant's questions. A typed confirmation reaches the latest card while nothing else has happened since: if an earlier "go ahead" of yours reached the assistant and it only reminded you to confirm, the next "do it" still confirms the card. Once you ask about something else, or the assistant looks something up or asks you a question, click the card's button instead. When one reply shows several cards, typing confirms none of them, because it can't know which one you mean; click each card you want. Typing never approves a call to a connected MCP server: that card takes a click, because what the server sends back is text an outside system wrote. See Approve a call.
Running your actions. The assistant can also run the actions a resource registers, not just write columns — see Your actions, from the chat.
Authorization is enforced at the tool layer, on every call. Each read and write goes through your Avo policies for the signed-in user who owns the chat — per-resource and per-field. Instructions are guidance for the model; your policies are what actually decides. A resource the user can't list is invisible to the assistant rather than refused, so it can't be used to probe for what exists.
Per-field means the policy's field lists too. A field the resource's policy withholds with whitelisted_fields / blacklisted_fields is not returned by any tool, not named in a record context or a confirmation card, and cannot be written. A column no field declares does not exist for the chat at all: it is not returned, filtered, sorted, grouped, searched, written, imported, or named in a schema, an inspector report or a validation message. What the panel shows or accepts without a field counts as declared: the timestamps or id a resource lists in discreet_information are readable, created_at stays a sort key whenever the column exists, and the columns a resource opens through extra_params are writable. Associations are reachable only through an association field the user may reach, and a model with no Avo resource is never queried or described. Undo reverses exactly what the chat did: a deleted record comes back whole, and an update or action is restored column for column, refused only where a restored column now belongs to a field the user may not write. Avo::Current.interface is :ai for the whole of a response and for a confirmed write, so a policy can withhold more from the chat than from the panel. See Field authorization.
The assistant reads the same rows the resource's Index shows: its index_query first, then the policy scope on top. Rows, counts, grouped answers, "has any" checks, and the records a write or action can target all stay inside that set, so tenant or soft-delete scoping you put in index_query bounds the chat too. Avo's show page finds a record through the policy alone, so a rule that must hold on every page still belongs in the policy's scope. Reading a row's field values, its files, or its chip fields also needs show? on that record: a row the user may list but not open comes back with only its id and reference.
Querying on a column reads it too. A filter, a "has any" check, a sort, a grouping, or a distinct count on a column the Index doesn't show matches, counts, and orders only the rows the user may open, so a row they can only list never reveals that column through which rows come back. Columns the Index shows filter every listed row as before, and sorting by created_at stays a sort the Index already does. To keep this bounded, a query that would have to check more than 1,000 listed rows is refused, and the assistant asks to narrow it with a filter on a column the list shows, a scope, or a search. A resource's own configured search runs as the admin runs it and isn't checked row by row. Without one, the assistant's search matches the text columns the Index shows on every row and the others only on rows the user may open; past the same 1,000 rows it searches the Index's columns alone rather than refusing. Without an authorization client every row opens, so none of this applies.
The chat runs in a background job, with no request. A resource whose field definitions read request-only context (Avo::Current.context[:account], params) can't have its field rules checked there, so the assistant refuses that resource rather than read it without them. A single field whose visible: proc raises is treated as hidden.
For the full reference — both agents, every tool and its gates, and how conversations get their names — see Agents and tools.
Record chips
A record the assistant mentions is drawn inline as a chip. By default it contains the record's picture and title, and clicking it opens the record. Resources can customize stable parts and let the assistant add current, answer-relevant Avo fields such as population or status. Sets of records render as full-width rows instead of inline chips.
See the Record chips guide to customize their content, appearance, dynamic fields, tooltips, and behavior in streamed or reloaded conversations.
Answering the assistant's questions
When the assistant genuinely can't proceed — a required value you didn't mention, or which of three matching records you meant — it asks you, and the question arrives as a card rather than as a sentence buried in a reply. The card is the message: the turn ends there and waits on you. It asks one thing at a time, and it asks instead of guessing; it won't use a question to chase optional values you never brought up.
A plain question. With no options to offer, the card is the question and nothing else. Answer it in the composer the way you'd answer anything else.
Question with options. When the answer is one of a small known set — a status, a yes/no, the titles of the records it matched — the card lists them, numbered 1, 2, 3…. Click one and it replies with that option's own text, so the conversation reads back as what you actually said ("Published"), not as an opaque "2". The numbers are there for typing: reply 2 in the composer and it lands on the second option.
The box beside them. Options are usually a shortcut rather than the whole truth, so most cards keep a free-text box next to them — Or answer in your own words… — with its own Send. When the options really are the entire answer space, the assistant closes that box off and the buttons become the only way to answer.
Picking several at once. Some questions take more than one answer — which fields to fill in, which of the matched records to include. Those render as checkboxes instead of buttons, with one Send under them and an Add anything else… box alongside. Everything goes back as a single reply: the labels you ticked, plus whatever you typed, separated by commas.
Answering a question card is an ordinary turn, never a confirmation. An option can quite legitimately read "Yes", and clicking it answers the question it belongs to — it can't reach back and confirm an update or a delete waiting further up the conversation.
Once you answer, the card settles. Its options come off and it goes flat, the way a write card does once you confirm it. The question itself stays above your reply — it is the transcript's record of what was asked — and a page you left open on that card can't answer the same question a second time.
Your actions, from the chat
Setting published_at is not the same as publishing. Your actions are where the operation actually lives — the notification it sends, the record it stamps, the service it calls — so the assistant runs them rather than reconstructing their effect field by field.
It works from the actions each resource registers. Nothing is exposed by default beyond what you already declare in def actions, and nothing extra is needed to opt in:
class Avo::Resources::Project < Avo::BaseResource
  def actions
    action Avo::Actions::ArchiveProject
  end
end
Ask for it in whatever words you'd use with a colleague — "archive the Orbit project" — and the assistant finds the matching action, reads the inputs it declares, and shows you a confirmation card naming the action and the record, with the action's own fields rendered right on the card. They're the same fields its modal would show — a tags field is a tags field here too — prefilled with the values the assistant took from your message and the action's own defaults. When you name a value it's the one on the card: "extend the trial by 3 days" lands 3 where the action would default to 7, "don't notify the user" leaves that box unchecked. Every field is editable before you run. Nothing runs until you confirm it — click Run, or tell the assistant to go ahead — and what runs is exactly what the fields hold at that moment; your confirmation executes it, not the model, exactly as with updates and deletes.
It collects rather than guesses. An input your action marks required: true that you didn't mention arrives on the card as an empty field for you to fill — the assistant never invents a value, because an action does real work with it. A run submitted with a required field still blank isn't performed; the card simply asks for it again.
The action's messages are the outcome. Whatever your action reports — succeed, warn, inform, error — lands on the card once it has run, each with its severity, the same messages the Avo UI would toast. An action may report several at once, and an error message is part of the outcome, not a failure of the run. The values the action was handed stay on the settled card too, folded behind a click.
Get the chat window out of the way. If your action leads the user somewhere else, or there's nothing left to say once it has run, call close_chat_window from handle and the window minimizes once the run is confirmed. The chat stays in the bar, one click away. Pass remove_from_bar: true to take it off the bar as well; the chat itself isn't deleted and stays in the recent-chats menu.
# app/avo/actions/publish_post.rb
class Avo::Actions::PublishPost < Avo::BaseAction
  def handle(query:, **)
    query.each { |post| post.update!(published_at: Time.current) }

    succeed "Published"
    close_chat_window
  end
endclose_chat_window(remove_from_bar: true)It composes with the other response methods: reload together with close_chat_window reloads the page and minimizes the window. Run from the Actions dropdown instead of the chat, the action ignores it.
Actions that run without records work too — the assistant runs them with no record at all.
It runs on the view it would have been started from. view is show when the run targets one record and index for a bulk run or one that takes no records — the page you would have clicked the action from, never new. The action's visible and authorize blocks, its fields, and handle all read that value, so an action that branches on view.show? or view.index? behaves in the chat as it does on a click. A display-only field the action declares, such as a badge or a key-value, shows read-only on the card beside the inputs, the way Avo's own modal renders it.
Finding an action without naming its resource
People ask in verbs. "Refresh the models", "send the welcome email", "export everything" — none of those name a resource, and none of them need to. The assistant can list every action registered across the application, each beside the resource that owns it, pick the one that matches what you asked, and run it from there.
This is why an action lands even when the noun in your sentence isn't one of your records. "Refresh the models" reads like a question about your database until you know that Avo::Resources::AvoAi::Model registers a Refresh models action — and knowing that is the assistant's job, not yours.
The list is scoped like everything else: it only contains actions from resources the signed-in user is allowed to list, so it can never surface an operation from a corner of the app that user can't reach. It's also fetched only when a request looks like an operation — a conversation about editing a blog post never pays for it.
An action two resources share needs you to say which
Naming the action alone is enough when one resource registers it. When two do, the assistant asks which resource you mean instead of choosing — two resources registering the same action class are two tables with two policies, and the run lands on exactly one of them.
What it's allowed to run
Two gates, both yours, both checked when the run is proposed and again when you confirm it:
act_on?on the record, the same policy method that decides whether the Actions dropdown appears in the UI. It's checked per record, so an owner-gated policy behaves in the chat exactly as it does on the page.- The action's own
self.visibleandself.authorizeblocks, evaluated with the record in place. An action the panel would hide from the signed-in user is left out of the assistant's lists too.
A policy with no act_on? refuses every action
act_on? fails closed. If a resource has a policy that doesn't define it, the assistant can't run that resource's actions — the same way Avo hides the Actions dropdown. Add act_on? to the policy to allow it.
A record id the signed-in user can't reach reports as "not found", never as "not allowed", so the chat can't be used to discover which records exist.
Undoing a run
Every run against a record is written to the same audit log as the assistant's other writes, and whether it can be undone is decided by what it actually left behind, not by what it claimed:
| The run… | In the history | Undo |
|---|---|---|
| changed columns on the record | recorded with a before/after diff | restores those columns |
| deleted the record | recorded as a delete | re-creates it |
| changed nothing you store | recorded, marked not undoable | not offered |
That last row is the point. An action that emails a customer or calls another service leaves nothing to restore, and the assistant says so plainly instead of offering an undo it can't honour. Even where an undo is offered, it restores the columns and nothing else — the card says as much before you confirm.
Standalone runs aren't written to the audit log at all: it records what happened to a record, and a standalone action has none. The card in the conversation is the record of it.
Tracing what it changed
The conversation keeps its own record of every write — that is what undo reads. With Audit Logging installed, the same write also lands in your app's audit log, where an admin reviewing the data will actually look for it: attributed to the user the chat acts as, and marked as coming from that chat.
| Column | Value |
|---|---|
author | The chat's owner |
origin | "ai_chat" |
origin_record | The chat |
A batch update is recorded the same way, one entry per record it changed, so an audit reader sees each record's own change. The conversation's history keeps the batch together: undo takes the whole batch back from one card, or only the records you name.
A record's timeline reads Ada Lovelace through AI chat; the activity's Origin field — AI chat — Reorder the Q3 invoices — links to the conversation; and the chat's admin page carries an Audit trail table of what the assistant changed there. An action run is recorded against the action, as a click on it would be; a revert is recorded as the write it is.
The table is gated by view_audit_trail? on your Avo::Ai::ChatPolicy, Avo's own convention for a has_many. The assistant itself can never reach the audit log: Avo::AuditLogging::Activity is not a resource it can name, list, or write to.
Files and attachments
The assistant reports on your Active Storage usage, so you can ask about files the way you ask about records:
| Ask | What you get |
|---|---|
| "How much storage are we using?" | Totals by storage service, content type, and resource |
| "Any orphaned uploads?" | Blobs attached to nothing — count, bytes, and the oldest one |
| "Do we have duplicate files?" | Files sharing a checksum, and the bytes de-duplicating would free |
| "Is storage growing?" | Uploads per month |
| "What are the biggest files?" | The largest files and which records they belong to |
| "Which products have no image?" | Records missing an attachment |
Ask it to show a file — "show me this post's cover", "what's on this product?" — and the reply carries the file itself: images render inline, video and audio get a player, and anything else comes back as a link that opens in a new tab.
You can also name the file instead of the record — "show me dummy-video.mp4", or just "show me the beach photo". The assistant searches for it across everything you're allowed to see and tells you which record each match belongs to, so you never have to know where a file lives before asking for it. Files sitting in the Media Library attached to nothing are searched too, and come back marked as such. Every file comes back with its blob id, which is what you reference when asking for a change.
It can also attach and detach files on a record — "attach blob 42 to this post's cover", "take the cover off this post". Files are referenced by their blob id, so the assistant links files already in your Media Library rather than uploading bytes itself. A Media Library URL carries that id — /avo/media-library/260/edit is blob 260 — so "attach 260 to this post's cover" works straight off the link.
Attach and detach apply immediately rather than through the confirmation card that record writes use. Detaching only unlinks the file — the blob stays in the Media Library and the assistant can re-attach it with the same id. Purging a file is never something the assistant can do; deleting the file itself stays a manual action.
Both respect your policies: file reports only count blobs attached to resources you are allowed to list, and attaching or detaching goes through the same upload_<name>? and delete_<name>? policy methods the Avo UI checks. The file itself is judged by who owns it, not by what the Media Library shows: the library lists every blob, but a file already attached to a record you're not allowed to read can't be attached from the chat — otherwise anyone could lift another user's private upload onto a record of their own and read it there.
Getting new files in
Two paths bring a file that isn't in your Media Library yet onto a record:
Upload it in the chat. Drop a file into the composer and send it — the assistant sees the file and knows its blob id, so "attach the file I just sent to this post's cover" is a one-step ask. Files uploaded this way are private to their conversation: the assistant can't reach uploads from anyone else's chats, and other users can't reach yours.
Give it a link. Ask the assistant to attach a file by URL — "attach https://example.com/logo.png as this post's cover" — and it proposes the download on a confirmation card showing the URL, the filename, and the record. When the link points at an image the card previews it, so you are approving a picture you have seen rather than an address you had to read. Nothing is fetched until you click Attach; the assistant can't fetch anything on its own, which is what keeps a malicious link that slipped into your data from ever being followed unseen.
The download itself is hardened: only public https:// URLs are accepted (private and internal addresses are rejected, on every redirect too), the file's content type is read from its bytes rather than trusted from the server, and anything over the configured size ceiling (25 MB by default) is refused mid-download rather than after it. If your files are bigger than that, or your source is slow, raise the matching keys under config.ai.remote_file — see Configuration. The undo is the same as for any attachment — detach it; the file stays in the Media Library.
Reading files and importing from them
The assistant can read the text of a file, not just show it: markdown, plain text, CSV, TSV, and JSON. "Read this contract and tell me if the subscription is active", "which of the emails in this CSV are signed-up users?" — it reads the file, pulls out what it needs, and queries your records with it.
The file can live in any of three places, and the read path is the same for all of them:
| The file is | It's readable when |
|---|---|
| Uploaded in this chat | Always — uploads are private to their conversation |
| Attached to a record | You're allowed to read that record |
| In the Media Library, attached to nothing | The Media Library is visible to you |
Files are named by blob id, as everywhere else in the chat, and a filename works when the assistant has no id yet: it searches everything you can see and reads the file if exactly one matches, otherwise it lists the candidates and asks.
Text uploads are read on demand, not sent inline. A markdown, text, CSV, TSV, or JSON file you drop into the composer is no longer pasted into the prompt whole. The model is told the file's name, type, size, and blob id, and reads it through read_file when it needs to — which is what keeps a 300-row CSV from flooding the conversation, and a much bigger one from failing the turn. Images, PDFs, and other non-text uploads keep going to the model as attachments, as before.
Reading happens in windows. Text, markdown, and JSON come back a range of lines at a time; CSV and TSV a range of rows, keyed by the header so column names survive into the answer. Every window reports the file's total, so the assistant knows to keep reading. One call returns at most max_slice lines or rows, and a file over max_read_size is refused with both sizes named rather than truncated quietly — raise the keys under config.ai.files if your files are bigger. See Configuration.
What a file says is data, not instructions. Content comes back framed as file content the user supplied, and a sentence inside a file addressed to the assistant carries no more authority than text in a record: it can be reported, never acted on. Only the standard text, CSV, and JSON parsers are used — no format that can execute code or deserialize objects is accepted, and spreadsheets and PDFs are refused with the accepted types named.
Importing records from a CSV is the write side of the same feature. "Create users from this CSV" reads the header and the first rows, works out which column fills which field — asking you when a required field has no obvious column — and then, instead of creating records one at a time, proposes the whole import as one card: the file and where it came from (this chat, a named record, or the Media Library), the resource, the row count, the column-to-field mapping, any columns it will skip, and a preview labelled as the first rows of the total.
Nothing is created until you click Confirm. The rows are then created on the server — the model never carries them, so the import costs a handful of turns whatever the row count — under the same authorization and field rules a single create uses, and the mapping is checked again at that moment against what you can write. A row that fails validation is skipped and reported on the card with its row number and reason; the rest are still created. When it's done the card reports how many records were created and lists the failed rows, and each created record lands in the write history like a single create, so any one of them can be undone on its own.
INFO
An import creates records only — updating or upserting from a file isn't offered — and it takes CSV and TSV files, not JSON. One import is capped at max_import_rows data rows (1,000 by default); a bigger file is refused with the count and the cap named, so split it and import it in parts.
Batch updates are capped too, at max_update_records records (50 by default). Raise it to at most 500; a higher value, zero, or anything that isn't an Integer raises at boot. An import's rows are new, so the only cost of a big one is the time it takes; a batch update changes records that already exist. However large it is, a batch counts as one entry in the undo history and is undone from one card. Checked rows stop at 50 whatever the cap is.
Teach the assistant your app
Out of the box the assistant knows Avo, not your application. It reads columns, enums, and scopes from its tools at run time, but nothing tells it that "customers" are User records with a role of client, that a "booking" is the Reservation resource, or that nobody on your team has ever asked about webhook deliveries. That's what it guesses wrong at, and guessing is what it has to do until you write the app down. That's why this is the last step of the install, not an extra.
Where you write it is a prompt file of its own, app/prompts/avo/ai/chat_agent/app_context.txt.erb. It renders into the system prompt on every turn, right after the assistant's identity and before the shipped rules — so the model reads who it is, then what it's embedded in, then how to behave. The gem's own copy renders to nothing, so nothing changes until the file exists.
Let your coding agent write it
The flow ships in the gem as an agent skill, avo-ai-onboarding. With the Avo skills loader installed, tell your coding agent:
Onboard the Avo AI assistant onto this app.It runs bin/rails avo:ai:inventory (below), reads your README and your initializer, tells you what it thinks the app is and asks whether it got that right, then interviews you in short rounds — a few related questions at a time, its best guess first — about the things the schema can't say. It writes the file once, at the end, after you've confirmed. Run it again after the app has changed and it proposes a diff rather than a rewrite.
The same interview settles what a record's status means here, which is exactly what a chip should carry — so it also proposes a def chip on the resources people look up, and a record the assistant names in the chat shows its status beside its title.
The inventory
bin/rails avo:ai:inventoryPrints a structure-only markdown brief of the admin: every Avo resource with its model, title attribute, fields, actions, filters, scopes, columns, enums, associations, attachments, policy, and whether it declares a chip; the application models that have no resource, which is what the assistant cannot see; which narrative files exist for an agent to read; and which prompt files you already override.
No record is ever read — columns come from the schema, scopes and enums from the classes — and columns or fields whose names read like credentials (password, token, secret, digest) are left out, because the brief is meant to end up in a file you commit.
It's the onboarding flow's starting point, and it's worth running on its own: it is the closest thing to a list of what the assistant can and cannot reach.
Writing it by hand
Eject the stub — its comment carries the rules:
bin/rails generate avo:ai:eject app_contextThen write down what the schema can't carry: what the app does, who uses the admin, what they call things, which resource each of those things lives in, and the questions people actually ask.
<%# app/prompts/avo/ai/chat_agent/app_context.txt.erb %>
Acme is a booking platform for photography studios. The people in this admin are
studio owners and our own support team.

Vocabulary:
- A "booking" is a Reservation. A "client" is a User with role "client"; a "host"
  is a User with role "owner".
- "Payouts" are Transfer records. Payments are what the client pays us — different
  resource, opposite direction.

What people ask here:
- Which reservations for a studio are still unconfirmed this week.
- Whether a host's payout for a given month has gone out.

Nobody asks about Webhook or AuditEntry records.
The file is ERB, with the same two locals as extra_instructions: user, the signed-in user the chat belongs to, and chat, the Avo::Ai::Chat record. A note that only applies to one role is a conditional here too.
WARNING
Structure only — never a record's values, a credential, or anything the people using the chat must not see. The rendered prompt is shown to every viewer whose debug level is :tools, and the file itself is committed. Instructions are guidance for the model, not a security boundary: what the assistant can actually read and write is decided by your Avo authorization policies.
app_context says what the app is. It's a different file from extra_instructions, which is the rules you want followed, and from identity, which is the assistant's name — writing one leaves the others alone.
Customize the assistant's instructions
The assistant's system prompt is built from ERB files that ship inside the gem, under app/prompts/. They resolve like Rails views: a file in your application at the same relative path replaces the gem's copy. If you configure nothing, the shipped prompt is used as is.
WARNING
Instructions are guidance for the model, not a security boundary. What the assistant can actually read and write is enforced by its tools and your Avo authorization policies — never rely on prompt text to hide or protect data.
Add your own instructions
To add rules on top of the shipped prompt, eject the extra_instructions file:
bin/rails generate avo:ai:eject extra_instructionsThis creates app/prompts/avo/ai/chat_agent/extra_instructions.txt.erb in your application. Whatever you write in it is appended right after the shipped rules, ahead of the blocks carrying the conversation's own context — the signed-in user, what the chat was started from, and the current time. The gem's own copy is empty, so until you edit the file nothing changes.
This is the place for the things the assistant can't learn from your schema:
<%# app/prompts/avo/ai/chat_agent/extra_instructions.txt.erb %>
Domain vocabulary:
- "Churned" customers are those with a cancelled subscription — use the
  Customer resource's cancelled scope, not a column filter.
- When the user says "orders", they mean the Purchase resource.

Style:
- Amounts are stored in cents. Always display them as EUR.
- Answer in the same language the user writes in.
The file is ERB, so you can interpolate anything your app knows — Rails.application.credentials, ENV, your own configuration. Two locals are also available: user, the signed-in user the chat belongs to, and chat, the Avo::Ai::Chat record. That makes per-role instructions a conditional:
<%# app/prompts/avo/ai/chat_agent/extra_instructions.txt.erb %>
<% if user.support_agent? %>
Only suggest read-only queries; never offer to change records.
<% end %>
Interpolate specific attributes — <%= user.first_name %> — never the whole object; only what you interpolate ends up in the prompt.
Rename the assistant
Out of the box the assistant introduces itself as Avo. Its name and one-line role live in a prompt file of their own, so you can rebrand it without replacing the rest of the instructions. Create the file at the same relative path in your application:
<%# app/prompts/avo/ai/chat_agent/identity.txt.erb %>
You are Ada, an assistant embedded in the Acme admin panel. You answer questions
about the application's data using the tools available to you. If the user asks
your name or who you are, say you are Ada.
Your copy replaces the shipped one entirely. Keep the "answer using your tools" sentence in some form — it anchors the assistant to the app's data — and change the name freely.
The avocado next to the name is a view, not a prompt — see Replace the assistant's icon.
Replace the shipped prompts
For full control, eject every prompt file the gem ships:
bin/rails generate avo:ai:eject instructionsThis copies all prompt files — the chat assistant's instructions and sub-prompts (identity.txt.erb, app_context.txt.erb, extra_instructions.txt.erb, skills.txt.erb, current_user.txt.erb, attached_context.txt.erb, uploaded_files.txt.erb, current_time.txt.erb), plus the conversation-renamer's — into app/prompts/avo/ai/, where your copies take over completely. Edit the ones you want to change and delete the rest: a deleted file falls back to the gem's copy, so you keep receiving prompt improvements for everything you didn't touch.
The shipped instructions.txt.erb renders those files through slots of its own, in this order:
| Slot | Renders | Changes |
|---|---|---|
<%= identity %> | who the assistant is | on deploy |
<%= app_context %> | what this app is | on deploy |
| the shipped rules | how the assistant behaves | on deploy |
<%= extra_instructions %> | your own rules | on deploy |
<%= skills %> | the skills attached to the conversation | when a skill is attached or edited |
<%= current_user %> | the signed-in user | once per conversation |
<%= attached_context %> | what the chat was started from | once per conversation |
<%= uploaded_files %> | the files in the conversation | when a file is uploaded |
<%= current_time %> | the current date and time | every message |
That order is least-volatile first, and it's deliberate: providers cache on a prefix of the prompt, so the first block that differs from the previous run invalidates everything after it. Lead with the clock and the whole prompt — the shipped rules included — is fresh input on every message. If your copy adds a block of its own, place it by how often it changes rather than at the bottom of the file.
If you replace instructions.txt.erb, your copy decides which of those slots survive — remove a line and that file is ignored, however carefully it was written.
Choose which tools the assistant gets
What the assistant can do is exactly the set of tools it's handed on each run. Two settings shape that set: excluded_tools takes shipped tools away, and extra_tools adds tools you wrote yourself.
# config/initializers/avo.rb
Avo.configure do |config|
  config.ai.excluded_tools = [:delete_record, :run_action]
  config.ai.extra_tools = ["CrmTool"]
end
Set neither and the assistant gets every tool the gem ships. The roster is assembled per run, so once the app has restarted, the next message in an existing conversation already reflects the change — nothing is baked into a chat.
Take a tool away
# config/initializers/avo.rb
config.ai.excluded_tools = [:delete_record, :update_record]
The names are wire names — what the model sees, and what every call is stored under on the message that made it (the Tool calls field on a message's show page). The tools table is the full list — ask_user, schema_inspector, resource_inspector, active_record_query, count_records, active_storage_insights, active_storage_attachment, read_file, create_skill, create_record, update_record, update_records, delete_record, run_action, import_records, write_history, rename_conversation; symbols and strings are both accepted.
update_record and update_records are separate names, so excluding the first leaves the second attached. An app that excludes update_record to stop the assistant writing columns wants both.
An excluded tool is filtered out by name before it's ever built, so it isn't attached to the conversation and the model never learns it exists. It doesn't refuse the request — there's nothing there to refuse with.
A name that isn't one of those raises ArgumentError at boot, listing the ones it knows. A typo that quietly left deletes attached is exactly the failure worth being loud about.
It's a denylist, so tools added later arrive switched on
excluded_tools says what to remove, not what to allow. A future avo-ai release that ships a new tool — a write tool included — hands it to every app that hasn't named it here. Read the release notes when you upgrade, and exclude anything you don't want.
Nothing is protected. ask_user and write_history are chat infrastructure rather than data tools, and excluding them is allowed: the assistant loses the ability to ask you a clarifying question, or to list and undo the writes it made in the conversation. That's a decision you're free to make — just make it deliberately.
Excluding resource_inspector costs less than it sounds like it should. The schema every result carries doesn't come from that tool, so queries and writes still work from your real columns and scopes. What you lose is the deeper report — field types, a resource's actions and filters, its associations and attachments — for the questions where the assistant wants structure a result can't give it.
Excluding rename_conversation turns AI titling off entirely
That tool is what applies a title, so removing it stops the conversation renamer too, not just the assistant's ability to rename on request: new conversations are no longer auto-titled after the first message, and Rename with AI stops having an effect. Conversations keep the Untitled chat placeholder until someone names them. Rename chat still works — that one never goes through a model.
The exception is a replacement: register your own tool under the rename_conversation wire name — which is exactly what ejecting it sets up — and titling continues through your copy.
Bring your own tool
Scaffold one:
bin/rails generate avo:ai:tool crmThat writes app/tools/crm_tool.rb, defining CrmTool — a RubyLLM::Tool the model calls crm. The file arrives with the same three mixins the shipped tools use, and TODOs where your part goes:
| Mixin | What it gives you |
|---|---|
Avo::Ai::ToolSupport | json_result for the reply shape, plus resource lookup and schema introspection helpers |
Avo::Ai::ToolAuthorization | The acting user, and the gates to reach data through: require_acting_user!, authorized_relation, authorize_record_action!, find_authorized_record_by_param |
Avo::Ai::InspectionAware | Answers with the touched resource's real columns, scopes, and required attributes under resource_schema — once per run per resource. It reads the resource name from your tool's own resource: argument |
Include InspectionAware in the tool class itself
It wraps your execute by prepending to the class it's included in. Included in a concern your tools share, the wrapper ends up behind each tool's own execute and never runs — no error, just results that quietly arrive without their schema.
Fill in the description — the model reads it to decide whether to call the tool, and a vague one is the usual reason a tool never gets called — then the parameters schema and execute.
A tool that writes a record goes through the resource's fields, as the shipped write tools do — never assign_attributes, Model.new(attrs) or update(attrs):
# app/tools/crm_tool.rb
scope = Avo::Ai::FieldScope.new(Avo::Resources::Contact, user: acting_user, view: :edit, record: contact)
refused = attributes.keys.map(&:to_s) - scope.writable_params.keys
return {error: "Not writable: #{refused.join(", ")}"} if refused.any?

scope.fill(contact, attributes) # runs each field's fill_field, as a panel save does
contact.save
Then register the class in your initializer:
# config/initializers/avo.rb
config.ai.extra_tools = ["CrmTool"]
A tool that takes settings of its own is registered as a Hash instead. Its tool: key names the class and every other key is passed to the tool's initializer:
# config/initializers/avo.rb
config.ai.extra_tools = [
  "CrmTool",
  {tool: "InvoiceTool", api_key: ENV["INVOICE_API_KEY"]}
]
Entries are class names, not constants: this initializer runs before your own classes are loadable, so the name is resolved when a chat runs. The upside is that reloading works normally in development; the trade-off is that a typo surfaces on a chat's first message rather than at boot — the chat's Agent tools field is where you'll read the error.
Three things the server decides for you, whatever the entry says:
- The acting user, the conversation, and the inspection tracker are injected server-side.
user:is passed to your initializer when it accepts one, andchat/inspection_trackerare set afterwards if your tool declares the accessors (the generated one declareschatand picks upinspection_trackerfromAvo::Ai::InspectionAware).user:,chat:andinspection_tracker:keys in anextra_toolsentry are stripped, so the initializer can't hand your tool a different user than the one who's chatting. - Authorization is yours to call. Nothing in the gem stops a tool reading the whole table — reach data through
authorized_relationandauthorize_record_action!so your tool sees exactly what the signed-in user sees in Avo, and rescueAvo::Ai::ToolAuthorization::IdentityErrorto report "not allowed" as a result instead of failing the run. - Two tools can't share a wire name. Registering a tool whose name collides with a shipped one raises when the roster is built. To replace a shipped tool, exclude it first — that's what ejecting does for you.
Returning records? Hand back a reference. Put the string that names each record in your result — "avo:#{short_name(resource_class)}/#{record.to_param}" — and the model copies it into its answer, where it renders as a chip. Build it from to_param, not id, so an app that hides its keys behind a slug or hashid keeps them hidden. When the model passes an id back to your tool, look it up with find_authorized_record_by_param(resource_class, model_class, id): it takes the param out of a reference, or a primary key the model selected, and reads either through the signed-in user's scope.
# app/tools/crm_tool.rb
def execute(resource:, id:)
  resource_class = find_resource_class(resource)
  return {error: "No #{resource} resource."} unless resource_class

  record = find_authorized_record_by_param(resource_class, resource_class.model_class, id)
  return {error: "No #{resource} #{id}."} unless record

  json_result(
    title: record.name,
    reference: "avo:#{short_name(resource_class)}/#{record.to_param}"
  )
end
Declare that id parameter as a string, since a slug is one.
What a tool returns goes to your model provider
Everything execute returns is sent to the provider on that turn and on every later turn of the conversation, and it's stored on the tool call. Return the minimum that answers the question — no API keys, no credentials, and no personal data the question didn't call for. Read secrets from ENV or Rails.application.credentials; never write one into the tool file or the initializer. When an entry fails to resolve, the error names the entry by its class and key names only — the values never reach a log, the error tracker, or the Agent tools field.
Serve the same tool over MCP
Running the MCP Server too? The class you just wrote can answer connected MCP clients as well. Declare which consent capability unlocks it — avo:read, avo:write or avo:actions — and the resources it touches, and register it with that gem beside this one:
# app/tools/crm_tool.rb
class CrmTool < RubyLLM::Tool
  def self.capability = "avo:read"
  def self.resources = %w[Ticket Project]
  # ...
end# config/initializers/avo.rb
config.ai.extra_tools = ["CrmTool"]
config.mcp_server.extra_tools = ["CrmTool"] The chat ignores both. A connection narrowed to named resources must grant everything resources lists, and refuses a call that names no resource. A tool that takes a resource: argument, like the execute above, is checked on the resource each call names, so list in resources only what it reads on every call. Over MCP the server injects the connecting admin as user: the way the chat does, runs the capability gate first, and serves a Hash as structured content, a String as text, and an {error: "..."} Hash as a tool error. chat and inspection_tracker are never set there, so a tool that can run over MCP mustn't depend on either. See Share a tool with Avo AI for the details.
This is MCP in the other direction
Here your app is the MCP server, and outside clients connect to it. To have the assistant call somebody else's MCP server from a chat, see Connect other tools with MCP.
Replace a shipped tool with your own copy
To change how a shipped tool behaves, eject it:
bin/rails generate avo:ai:eject tool delete_recordThis copies the gem's tool into app/tools/delete_record_tool.rb as a plain top-level class you own, then wires both halves of the swap into the Avo.configure block in config/initializers/avo.rb:
# config/initializers/avo.rb
# delete_record ejected to app/tools/delete_record_tool.rb — the copy replaces the tool avo-ai ships.
config.ai.excluded_tools += ["delete_record"]
config.ai.extra_tools += ["DeleteRecordTool"]
Both lines are needed, and neither works alone: the exclusion takes the shipped tool away, and the extra entry puts your copy back under the same wire name. The copy keeps its def self.tool_name, so tool calls, icons, and result cards are unchanged — to the model and to your stored history, it's still delete_record.
A tool the gem builds with an argument of its own is registered carrying it, so your copy is constructed exactly as the shipped one was. Ejecting rename_conversation writes {tool: "RenameConversationTool", rescan: true} for that reason.
The generator refuses rather than surprising you. It won't overwrite an existing app/tools/… file, and it won't run twice — an initializer that already excludes the name is read as "ejected already", and nothing is written.
An ejected copy stops receiving gem updates
It's a fork. Every later fix that lands in avo-ai's own copy — authorization hardening included — stays there. Diff yours against the gem's app/tools/avo/ai/<tool>_tool.rb when you upgrade, and eject only the tools you actually mean to change.
If the generator can't find your Avo.configure block
It won't edit an initializer it doesn't recognize — a mangled initializer takes the app down at boot. Instead it prints the two lines, exits with a non-zero status, and says so: the copy is on disk but is not active. Until you paste those lines into config/initializers/avo.rb yourself, the assistant keeps calling the tool the gem ships, not yours.
See what a conversation will get
Open a chat in the Chats resource and read its Agent tools field: it's computed by the same code the chat runs, for that chat's owner and model, so it's the answer to "did my configuration take effect?" See Seeing a conversation's roster for how to read an empty or unexpected list.
Replace the assistant's icon
The assistant's mark is two partials:
| Partial | Rendered on |
|---|---|
avo/ai/_pit_core_icon | The Agent button, the round button the dock collapses to when you hide the toolbar, and the full-page new-chat page |
avo/ai/_avocado_icon | The greeting above a chat with no messages yet, the empty chat list, and the Open in assistant bar button on a chat's record page |
Create the same paths in your application and every place that renders them changes at once. Override both to rebrand the assistant everywhere:
<%# app/views/avo/ai/_pit_core_icon.html.erb %>
<%= svg "tabler/outline/robot", class: local_assigns[:classes] %><%# app/views/avo/ai/_avocado_icon.html.erb %>
<%= svg "tabler/outline/robot", class: local_assigns.fetch(:classes, "size-4") %>An image file works the same way:
<%# app/views/avo/ai/_avocado_icon.html.erb %>
<%= image_tag "assistant-mark.svg", class: local_assigns.fetch(:classes, "size-4") %>
Each place that renders an icon passes a classes local, because the sizes differ: size-5 on the Agent button and size-7 on the new-chat page for _pit_core_icon, size-6 on the empty states and size-4 on the record page for _avocado_icon. Pass it through to whatever you render, as the examples do, or the icon comes out the wrong size in half of them. Don't add a size utility of your own to _pit_core_icon: on the collapsed dock's button the stylesheet sizes the mark as a share of the button so it grows with it, and a size class in your markup outranks that rule.
The icon on the chat pages' breadcrumb isn't part of the partial and stays an avocado.
What you start the chat from
Start a conversation from a page whose subject is one thing and the assistant already knows what you mean. You can ask "who owns this?", "what is this?", or "rename this to Q3 pricing" without naming it or waiting for a lookup. Three kinds of page carry a subject:
| Started from | What the chat carries | What "this", "it", or a question with no subject resolves to |
|---|---|---|
| A record's page | The resource name and the record id | That record |
| A Media Library file's page | The Active Storage blob id | That file |
| A conversation's page | The chat, itself a record | That conversation |
| Any Avo page | That page's title and path | The page itself, for "what is this page?" |
| A page with rows checked | Every checked row, by resource and id | Those records, for "these" and "the selected ones" |
The last two are not subjects of their own — they ride along with whichever subject the page has, and with each other. A record's page carries the record and the page; a course's page with three links checked in a has-many panel carries the course, the page, and the links.
A ribbon above the composer shows exactly what a new chat will carry, so it's never a guess: the subject, the page's path, and how many rows are checked. A record shows its avatar or its initials — the same pair the breadcrumbs show — and a file shows its own thumbnail when it has one.
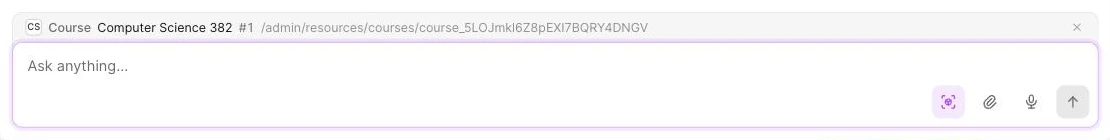
It is one ribbon with one ✕: "what is this about" and "where was I" are not two decisions worth making separately. An index, a dashboard or a new-record form has no subject of its own, but it still has a page and it may have rows checked, so the ribbon is there too.
What is attached stays attached for the whole conversation. It's what the chat was started from, so you're asked once, when the chat begins — that's why the ribbon is on the new-chat composer only. Every later message still resolves "this record", "this file", "it", or a question with no subject at all against the same thing. Ask "what is this?" as the fifth message and it works exactly as it does as the first.
Dismiss the ribbon with the ✕ at its end, or press Backspace in an empty composer, and the chat starts without it. Press Backspace again and the subject is attached back. Holding the key down to clear a message never reaches the ribbon — only a fresh press in an already-empty composer counts. The button next to send is the same switch, and lights up whenever the subject is attached, so the ribbon and the button always agree about what the chat will carry. Every fresh compose view offers the subject again: the ✕ applies to the chat you're writing, not to the feature.
It respects your policies, on every message. Only references are kept — a resource name and a record id, a blob id, a title and a path — never a field value, and never the labels you see in the ribbon. That reference is resolved again on each turn, through the same authorization the page itself applies — index? plus your Pundit scope for a record, Media Library access for a file — and the label is read fresh at that moment. So a subject the user loses access to, or that gets deleted mid-conversation, simply drops out of the prompt instead of lingering as a stale copy of something they can no longer see. A checked row that was never theirs to read is not attached at all — the chat carries the subset they could have selected in the UI, never the set the browser asked for. The attachment is only a starting point either way — every read and write the assistant then performs is authorized on its own.
Starting from a Media Library file
Open one file in the Media Library and start a chat from its page: that file is the subject. "What is this?", "where is this used?", and "attach this to the latest post" all resolve to it — and "where is this used?" comes back naming every record the file is attached to, which is the question a file's page most often raises.
The gate is Media Library access, and it's the same one the page itself applies: a user who can open the library can open any file's page in it, so there is no narrower per-file check to add on top. Turn the Media Library off, or narrow its visible block to fewer admins, and the file drops out of every prompt at once rather than the context outliving the access it was granted under.
Only the blob id is stored. The filename and content type are read off the blob on each turn, so a file renamed mid-conversation is named correctly on the very next message.
Starting from a conversation
A chat is stored as a record, so its own page offers it the way any record's page does. Open a conversation, start a new chat from the bar, and "summarize this", "what did we decide here?", or "who was this with?" resolve to the conversation you were reading — no copying and pasting a transcript into the new chat.
The rows you checked
Check rows on an index and they come with the message, so "email these people", "how many of these are unpaid?", or "delete them" resolve to ids instead of another search.
Every index on the page counts, not only the one the page is named for. A has-many panel on a record's page is an index in its own right, so on a course's page you can check three links and ask "what are these?" — the course and the links both travel, each addressed by its own resource. Check rows across two panels and the chat carries all of them: two links and four attendees is one selection of six.
Hover the "3 records selected" chip — or focus it, if you are on the keyboard — to see exactly what is attached, by resource and by name. Those are the same labels the assistant will see.
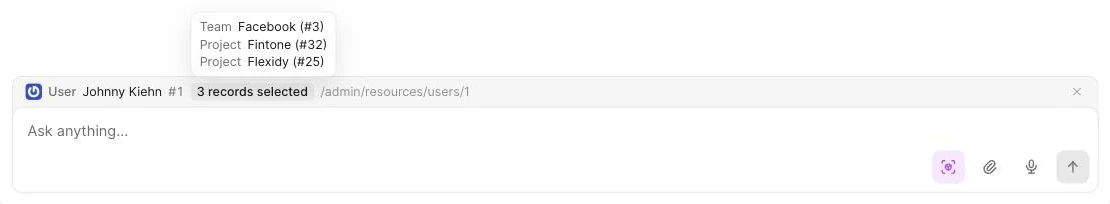
Up to 50 rows travel with one message. Past that the assistant is told the list was cut, so it says so before acting on "all of them" rather than quietly working from the first 50.
A selection is also what you batch over: "set all of these to archived" proposes one card covering exactly the rows you checked. At the default max_update_records of 50 the two limits match, and they match on purpose: both keep a batch small enough to review on one card.
INFO
Rows of an array resource can't be attached — they have no database record to authorize or act on, so they are left out of the selection.
The page you were on
Every Avo page contributes its own title and path. That is what makes "what is this page?" or "where am I?" answerable on a dashboard, a settings page, or a filtered index — pages that are nobody's record.
The assistant's own pages are the exception. A chat you start from the new-chat page, the chat list, or a conversation carries no page origin — the compose box is where you write a chat, never what it is about. A conversation's page still offers the conversation itself, as the record it is.
It is a label, not a description: the page origin says where the conversation started and never what was on screen. The assistant still queries before stating anything about your data, and page titles are passed to the model as untrusted values, so a record whose name reads like an instruction is text rather than a command.
Change how it reads
The wording lives in a prompt file like the rest, so you can change how the assistant treats any of it:
bin/rails generate avo:ai:eject instructionsThen edit app/prompts/avo/ai/chat_agent/attached_context.txt.erb. It receives one local per source, each nil when the conversation did not start from that thing:
| Local | Shape | Present on |
|---|---|---|
attached_record | {resource:, record_id:, record_param:, label:} | A record's page |
attached_file | {blob_id:, filename:, content_type:} | A Media Library file's page |
attached_page | {title:, path:} | Any Avo page |
attached_selection | {groups: [{resource:, records: [{record_id:, record_param:, label:}]}], capped:} | A page with rows checked |
A page offers at most one of the first two. Rendering nothing is a valid way to turn any of it off.
Name a record by record_param, its to_param. record_id is the primary key the chat stores, and an app that hides its keys behind a slug would see it in the prompt, and in anything the assistant repeats from it. The tools accept either.
Open the chat
The chat bar sits at the bottom of every Avo page. Cmd+J on macOS (Ctrl+J elsewhere) opens it from anywhere, including from inside a field you're typing in — that's the point, so you can pull the assistant up mid-edit without losing your place. Clicking Agent does the same.
On smaller screens, opening the sidebar temporarily hides the chat bar so the profile menu stays reachable. Closing the sidebar restores the bar without clearing your conversation or draft.
Every chat you open becomes a pill in the dock, newest first, so several conversations can stay open at once and you can switch between them without losing any. Drag a pill to reorder them. The chat window lines its end edge up with the pill it was opened from and slides across when you switch, so it's always clear which conversation you're looking at. The chevron at the bar's end collapses the whole dock down to that one button when you want the page to yourself; click it again to bring the bar back. The open chats, their order, and the collapsed state are all remembered per device.
Clicking the window's own title bar minimizes it — the conversation stays in the dock, it just gets out of your way. The × in the title bar does the same thing: it closes the window, not the conversation. To take a chat out of the dock, use the × on its own pill; the conversation itself is kept either way, and it's still on your chat list.
The window sizes itself to the screen, and remembers what you drag it to. Its default size is a share of the viewport rather than a fixed box: floored so a laptop still gets a usable panel, capped so a large monitor doesn't hand the chat half the page. Drag its top edge, its start edge, or the corner between them to resize it. The size you land on is kept per device and restored on your next page load, shrunk to fit if you come back on a smaller screen. The window never reaches under Avo's top navbar, however far you drag.
To clear the dock in one go, open the history menu (the clock button next to Agent) and pick Clear open chats at the bottom. It does what every pill's × does, all at once, and closes the chat window: the pills go, and every conversation stays in the history list right above the button, one click from reopening. The entry only shows when there's at least one pill to close.
Use only full-page chats
To offer AI chat only through your menu, disable the floating bar in your initializer:
# config/initializers/avo.rb
Avo.configure do |config|
  config.ai.chat_bar_enabled = false
end
The bar is enabled by default. Setting this to false removes the dock, its Cmd+J / Ctrl+J shortcut, and the controls that open or minimize a conversation into the bar. Full-page chats, their composers, and existing conversations remain available.
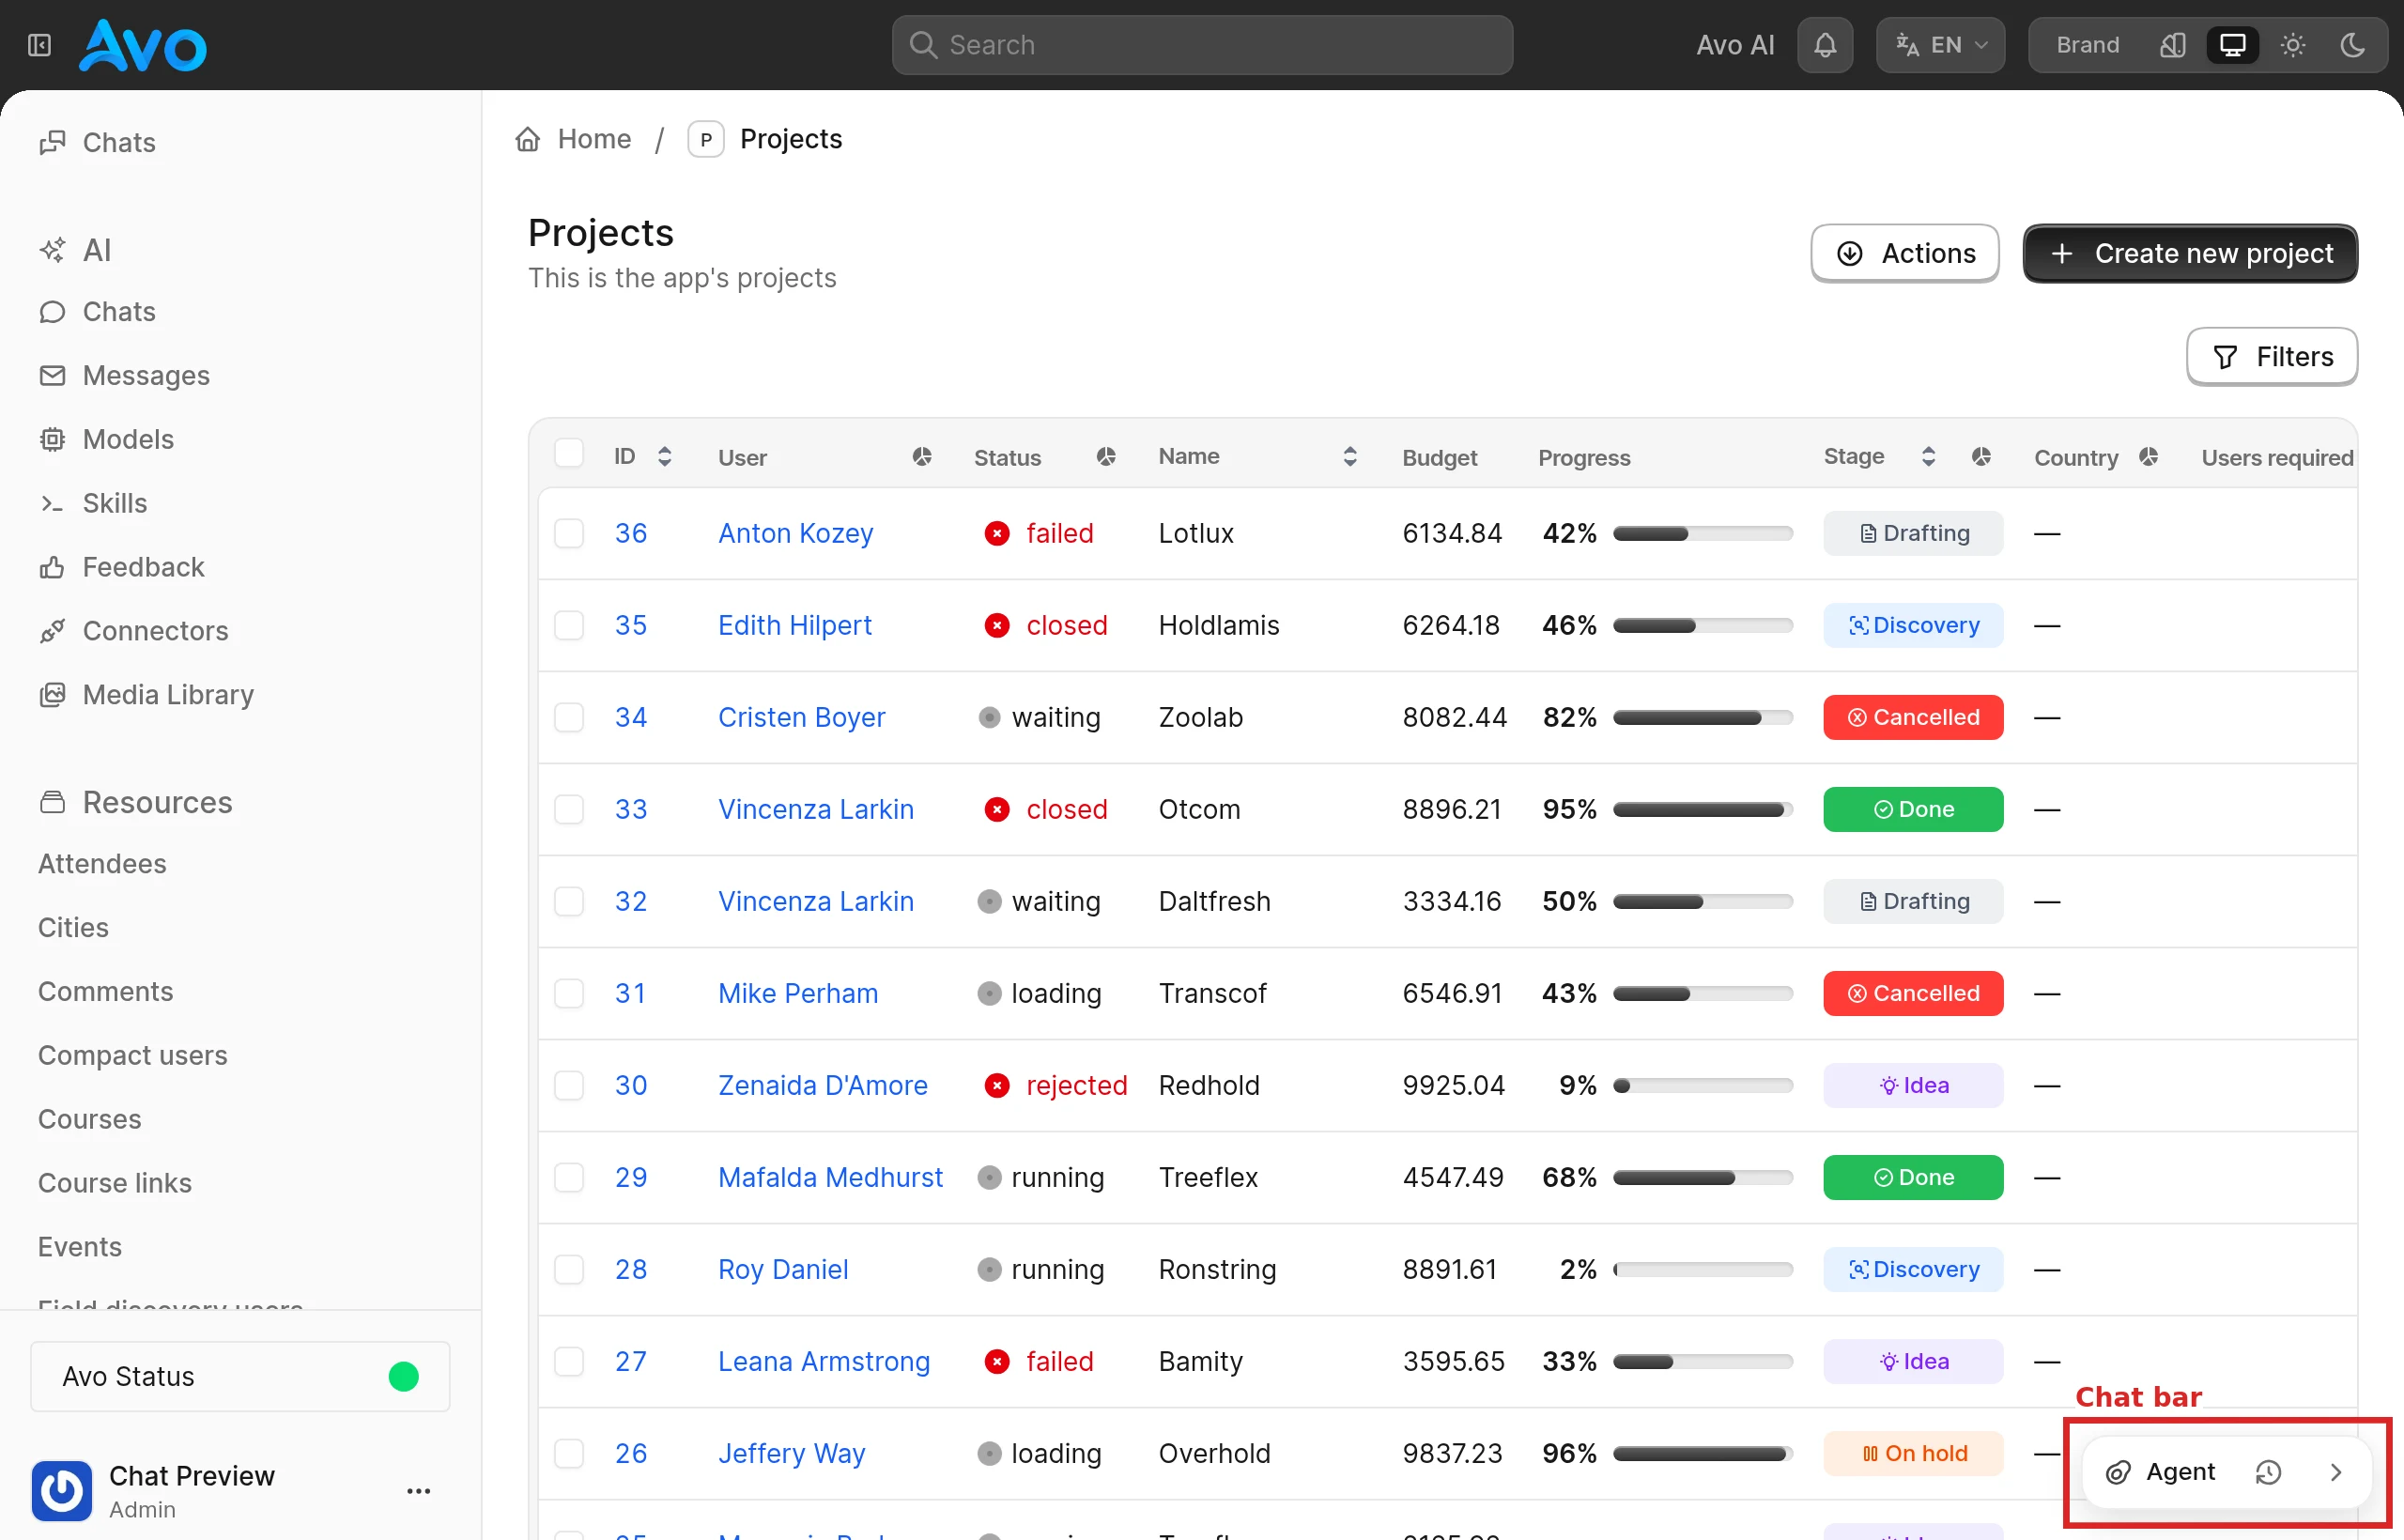
With the default configuration, the floating Agent dock appears on resource pages too. The red outline highlights it in the bottom-right corner of this Projects page:
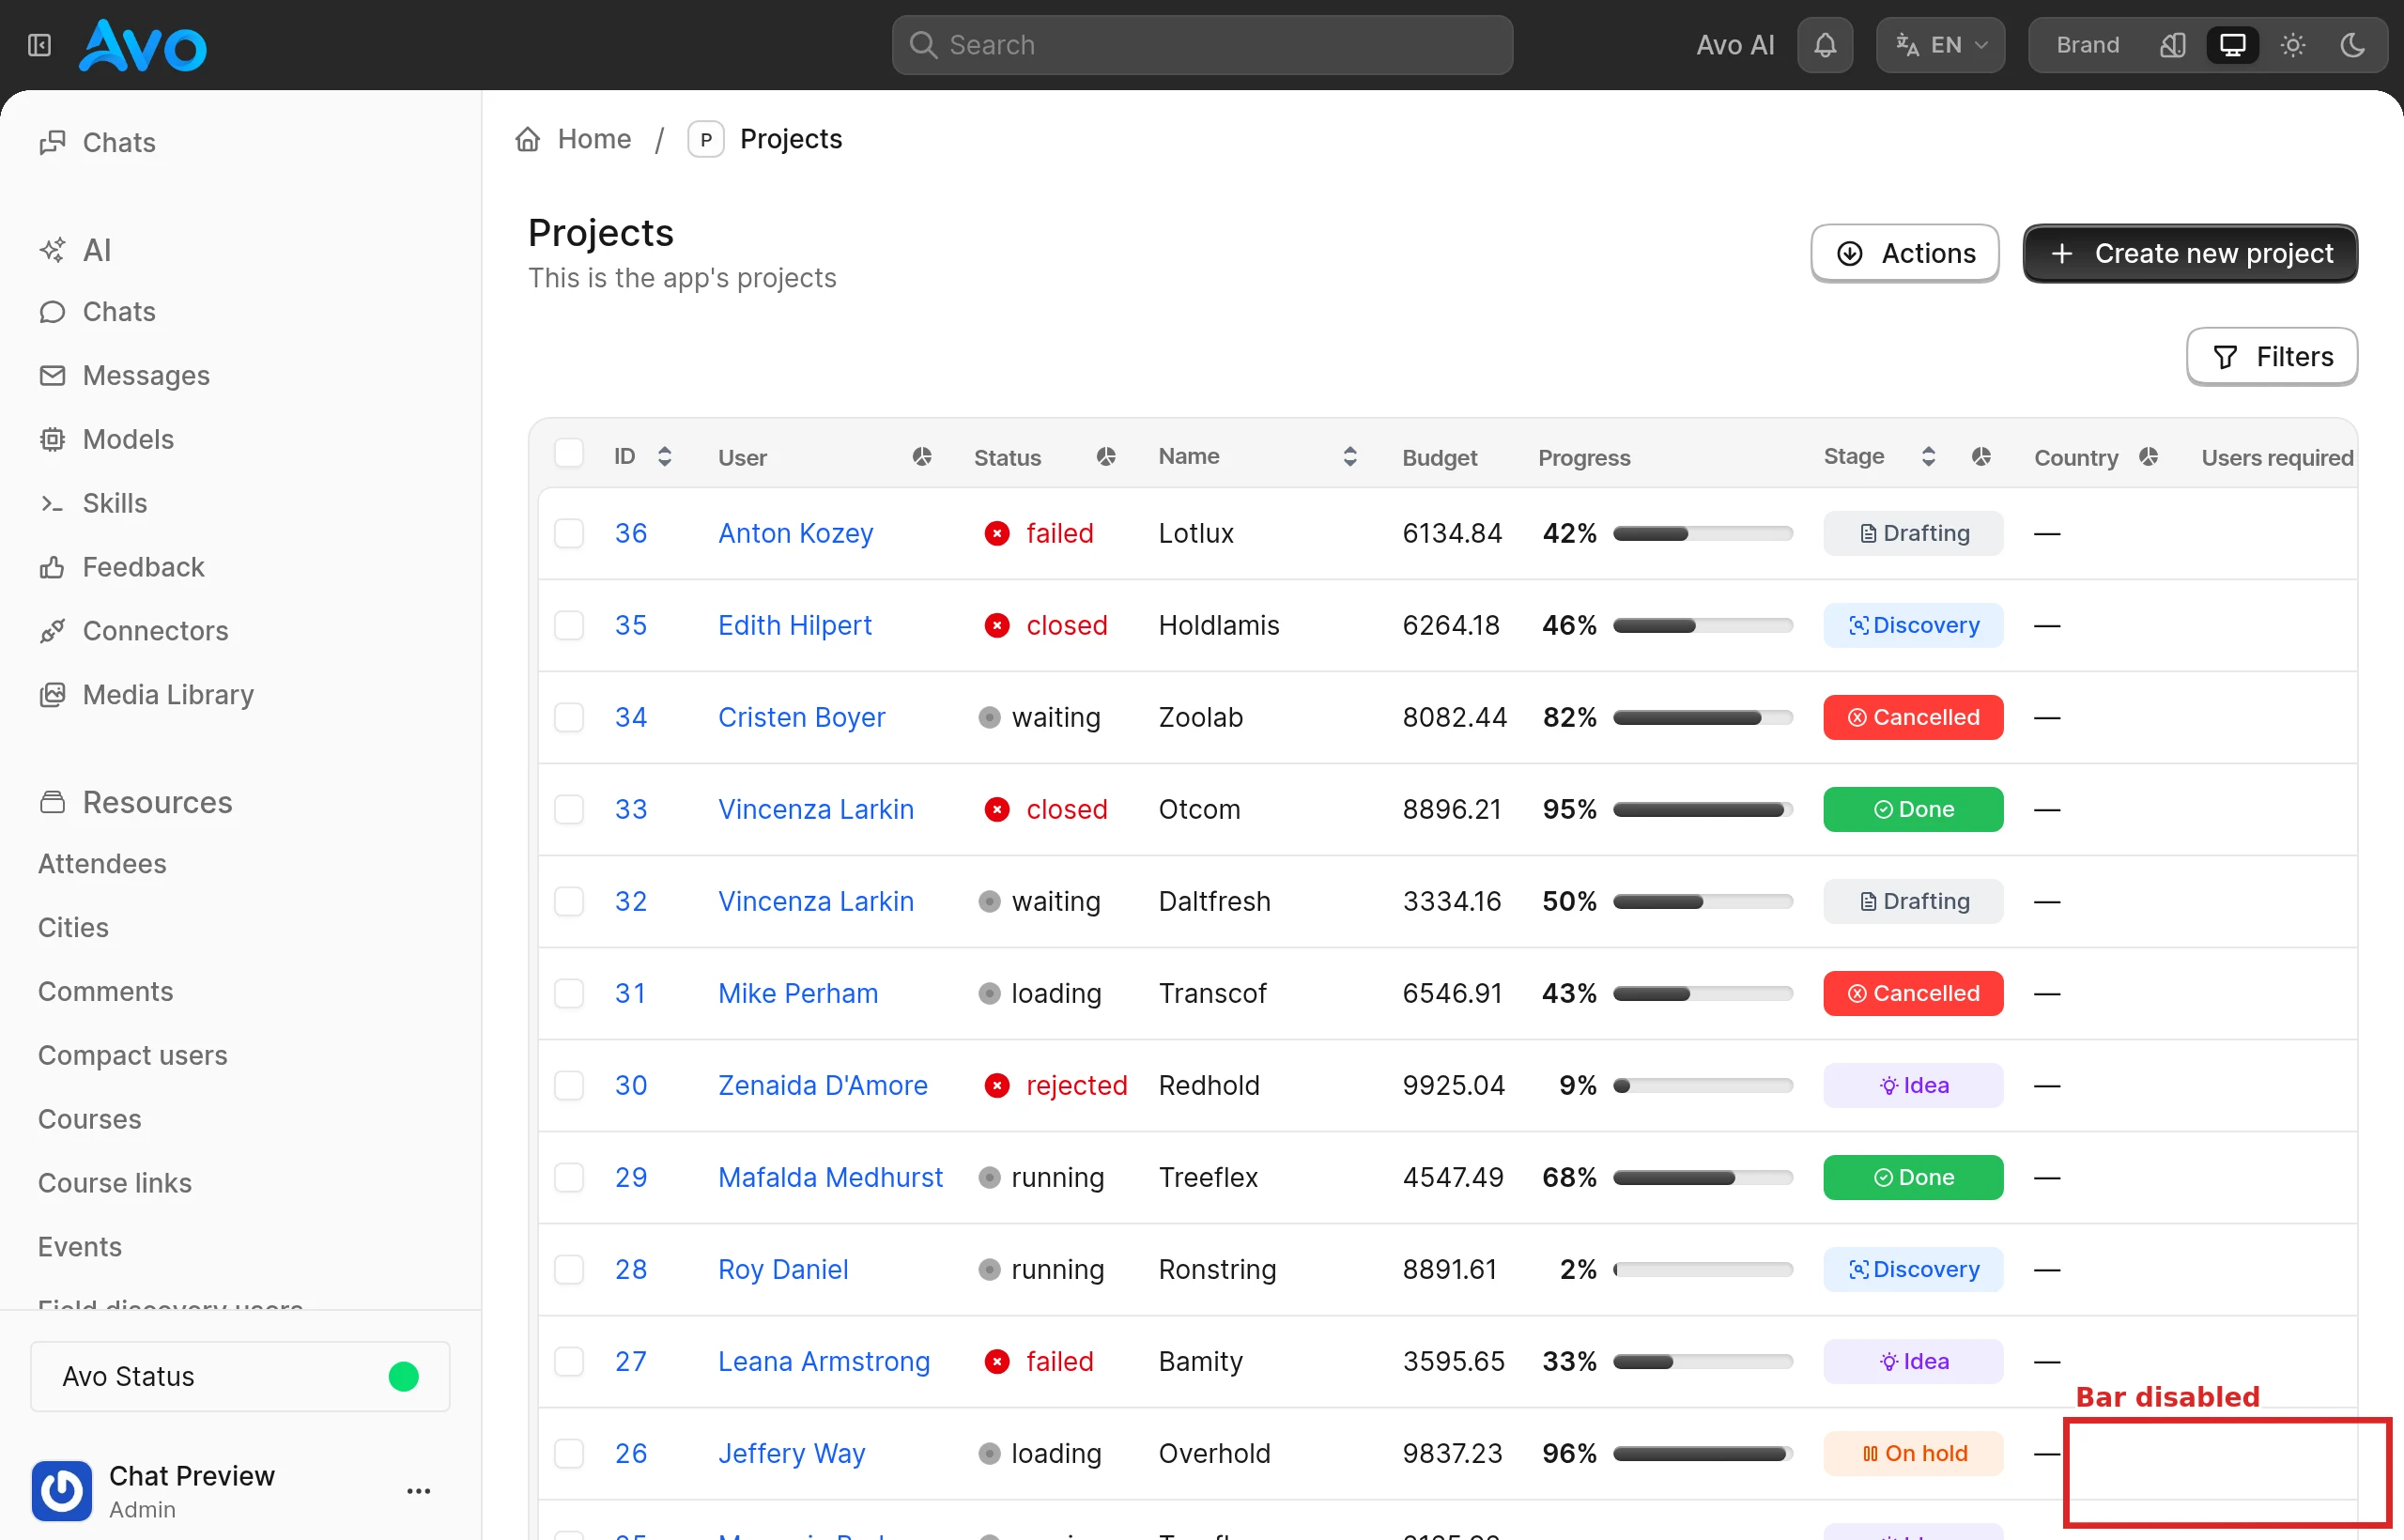
With config.ai.chat_bar_enabled = false, the same page has no floating dock. The red outline marks where it used to be. The Chats link in the sidebar still opens the full-page chat list:
Add a link to the end-user chat list inside your config.main_menu block:
# config/initializers/avo.rb
link "AI chat", path: "/admin/chats", icon: "tabler/outline/message"
Replace /admin if your Avo mount path differs. This opens the full-page chat product, not the avo_ai/chats resource used by super admins to inspect raw chat records.
Closing idle tabs automatically
Pills you stop using pile up. Set config.ai.tab_expiry and a pill nobody has opened for that long closes itself the next time an Avo page loads:
# config/initializers/avo.rb
config.ai.tab_expiry = 30.days
It takes a duration or a number of seconds. It's unset by default, which keeps pills until someone closes them. To turn it back off, set it to nil or false (or delete the line):
config.ai.tab_expiry = false # pills stay until closedZero, a negative value, true, or anything else that isn't a number raises at boot. The clock restarts every time a pill's conversation is shown, and pills opened before you upgraded count as fresh rather than expiring on the first load. As with Clear open chats, only the pill goes — the conversation stays in the history menu and on your chat list.
To give a conversation the whole window, use Open in full page in the title bar. It's a normal link, so cmd-click opens it in a new tab. From that page, Minimize to the chat bar hands the conversation back to the floating bar. If you got there through Open in full page, it returns you to the page you came from and its tooltip names it; a chat page opened directly — from a link, the chat list, or a bookmark — has no such page, so it takes you home instead.
The button is there before you've sent anything, too. On the new-chat view it points at the full-page composer instead, so you can start a long message with the whole window rather than the panel.
A new conversation opens with a short greeting and a few suggested prompts. Clicking a suggestion types it into the composer and submits it — it takes exactly the same path as a typed message. The greeting text is translated through i18n (avo.ai.empty_state.title / .subtitle) like any other copy; the suggested prompts themselves are generic by default but can be replaced with your own via config.ai.empty_state_suggestions.
INFO
The shortcut is ai.toggle_assistant in Avo's hotkey settings. If you've set config.hotkeys = {enabled: false} in config/initializers/avo.rb, it is off along with the rest — the Agent button still works — and you can rebind or disable it on its own through config.hotkeys[:bindings].
Full-page chats
Chats are also real pages, at /chats under your Avo mount point (/avo/chats with the default mount). The list shows every chat you own — its model, message count, and age — and links to the conversation. It's the same chat as in the bar: same messages, same tools, same streaming, with room to read.
The list is scoped to the signed-in user. It's not an admin view of everyone's conversations — for that, browse the Avo::Ai::Chat resource from the sidebar.
Avo's resource hotkeys work here too: C starts a new chat from the list or from a conversation, and I takes you from a conversation back to the list. They are resource.new and resource.go_to_index, so a rebinding in config.hotkeys[:bindings] applies here as well.
The conversation menu
The ⋯ button next to a conversation's title opens its menu. It's in the chat window's title bar and on the full-page chat, and both carry the same two rename entries:
- Rename chat makes the title editable in place — the panel's header in the bar, the last breadcrumb on a chat page. Enter commits and Esc cancels in both. Clicking away differs: in the bar it cancels the edit, on the chat page it commits it. An empty title is refused, so a conversation always keeps a name.
- Rename with AI hands the conversation back to the renamer agent for a fresh title, without going through the assistant. The title shimmers while the renamer runs, and the new name lands everywhere the old one showed.
Renaming needs no policy of its own — owning the chat is the entire permission, and you only ever see your own.
The bar's menu carries one more entry. Copy as markdown puts the whole conversation on your clipboard as plain markdown: the chat's title as a heading, then every turn labelled User: or Assistant:. Only what was actually said is copied — tool cards, confirmation cards, and debug rows stay behind, so what you paste into an issue or a PR is the conversation, not the machinery.
The menu's other entries have their own sections: deleting a chat, and — for viewers whose policy allows it — the debug toggle.
Write a message
The composer is a rich text box, not a bare textarea. The usual markdown shortcuts work as you type — **bold**, # heading, - list, backticks for code — and formatting survives a paste. Enter sends the message, Shift+Enter starts a new line, and on an empty composer Up recalls your previously sent messages, shell-style. The assistant receives the message as markdown, structure intact.
Send files with a message
Every composer takes files: click the paperclip, drag them in, or paste them from the clipboard. Files upload as you add them — through Active Storage's direct upload, into the storage service your app already uses — preview in the draft, and go to the model with the message, so "summarize the attached CSV" and "what's in this screenshot?" work the way you'd expect.
The files stay attached to the message and the model sees them again on every later turn — you can keep asking about a file for the rest of the conversation, not just in the message it rode in on.
Each file shows as a chip under your message. Clicking an image or a PDF opens the file; clicking a text file — markdown, plain text, CSV, TSV, JSON — opens its Media Library page, where the blob id, the download, and the delete live. When the Media Library is disabled the chip downloads the file instead.
Text files — markdown, plain text, CSV, TSV, and JSON — take a different route from images and PDFs: they aren't sent to the model inline. The model learns the file's name, type, size, and blob id, and reads it in windows through the read_file tool when it needs the content. See Reading files and importing from them.
The one thing to check is the model: reading an image takes a vision model. The current Claude, GPT, and Gemini families all read images and PDFs; sending a file to a model that can't read it fails at request time with the provider's error rather than silently dropping the file.
What the composer accepts
By default the composer takes what the assistant can do something with: images (PNG, JPEG, GIF, WebP) and PDFs, which go to the model, and text files - markdown, plain text, CSV, TSV, JSON - which it reads in windows. Files can be up to 25 MB.
Anything else is refused as you add it, before it uploads, with a line under the draft naming the file and why — so a 2 GB video never leaves the browser. The same rule is checked again when the message is sent, so a request that skips the composer can't attach a file it would have refused.
Change either side under config.ai.uploads:
# config/initializers/avo.rb
Avo.configure do |config|
  config.ai.uploads = {
    max_size: 50.megabytes,
    # Keeps the defaults and adds Word documents, e.g. for attaching to records.
    accept: %w[image/png image/jpeg image/gif image/webp application/pdf text/* application/json
      .md .markdown .txt .csv .tsv .json
      application/vnd.openxmlformats-officedocument.wordprocessingml.document .docx]
  }
end
accept reads like the HTML accept attribute, because that is where it ends up — the paperclip's file dialog is narrowed to it. Entries are MIME types (application/pdf), wildcards (image/*) or extensions (.csv), and a file passes when its type or its extension matches. The extensions matter: browsers often hand over a .md or .tsv with no type at all. Use ["*/*"] to allow any file — for example when people upload files only to have the assistant attach them to records. A malformed entry ("pdf") or an empty list raises at boot.
INFO
Setting accept replaces the list rather than adding to it, so repeat the defaults you want to keep.
Protect the direct-upload endpoint
The composer uploads through Rails' own direct-upload endpoint, POST /rails/active_storage/direct_uploads. Rails ships that endpoint without authentication: anyone who can load a page from your app can create blobs of any declared size and get a URL to upload them to. That is true whether or not you use Avo AI — the composer's limits run in the browser and at send time, and neither stops a request that goes straight to the endpoint.
Protecting it is your app's job, because only your app knows who is signed in. The smallest fix is a before_action on Rails' controller, using your app's own authentication and size limit:
# config/initializers/active_storage.rb
Rails.application.config.to_prepare do
  ActiveStorage::DirectUploadsController.class_eval do
    # Devise's helper — use whatever your app authenticates with.
    before_action :authenticate_user!

    # The composer's own ceiling. Raise it if other upload fields in your app need more.
    before_action do
      if params.dig(:blob, :byte_size).to_i > Avo.configuration.ai.uploads[:max_size]
        head :content_too_large
      end
    end
  end
end
to_prepare re-applies it whenever development reloads code. With this in place, a signed-out request gets a 401, an oversized one a 413, and the composer works as before. Checking the declared size is enough on the Disk and S3 services, which refuse an upload whose body is a different length; on another service, check that it enforces the declared length too.
Attach a skill with a message
A skill is a reusable instruction — a title, an optional one-line description, and a markdown body, written once by an admin and dropped into any chat. The description is for the person choosing and is never sent to the assistant. Type / at the start of a line or after a space to open a menu of every skill you're allowed to see, filtered by title and description as you type; pick one with the keyboard or a click and it lands in the composer as a chip. The Skills dropdown in the composer's toolbar, beside the model picker, lists the same skills and inserts the same chip at the cursor, for anyone who'd rather not remember the slash. It only appears once there's a skill to pick. Backspace removes the whole chip in one press, never one letter of its title.
Write around the chip, or send it on its own — a message that's nothing but a skill chip is a valid send, the way a /-style slash command carries its own instruction. In the sent bubble the chip renders like any other record chip and links to the skill's page. Hover a skill chip, in the draft or in the transcript, to read its description.
Picking a skill isn't a one-turn thing: its body joins the assistant's instructions for the rest of the conversation, and every later message in that chat reuses it too. Attach a second skill later and both apply together — there's no per-message detach in this version.
The body is read fresh on every turn, never copied into the message. Edit a skill and the change reaches the very next reply. Delete it — or lose access to it through the skill policy's scope, see Choose who can manage skills — and it silently stops applying, in every chat that ever referenced it. Only the chip notices: a deleted skill's chip in an earlier bubble falls back to plain text, carrying the title as it was when you sent it.
A message that's only a chip is an instruction to run, now. Send "Summarize as changelog" with nothing else typed around it, and the assistant treats that turn as doing what the skill says, on the spot — not describing the skill back to you.
Manage skills from the AI Skills resource in the sidebar — see Choose who can manage skills for the menu entry and who's allowed to create, edit, and delete them.
Import a skill
Already have the skill written down? Click Import skill on the AI Skills index and paste the markdown. A frontmatter block at the top supplies the title and the description; everything under it becomes the body:
---
title: Changelog
description: Summarise a record as a changelog entry
---

Summarise the attached record as a changelog entry…
name works in place of title, so an agent SKILL.md pastes in unchanged. Other frontmatter keys are ignored. Without frontmatter there is no title to read, and the import says so rather than guessing one. Importing is creating — the action is available to whoever passes create? on the skill policy.
You can also ask the chat to "Add this as a skill", followed by the skill's text, or upload a .md or .txt file and ask "Import the attached file as a skill". The assistant proposes it through create_skill, and a card shows the title, the description and the full text. Nothing is saved until you click Save skill, because a skill's text becomes instructions for every chat that picks it. The skill policy's create? permission is checked when the card is proposed and again when you confirm it. Files are imported directly from this conversation, without the assistant rewriting their contents. For plain instructions without frontmatter, give a title or let the assistant supply one. An existing skill with the same title is never overwritten.
Only .md and .txt files are supported; create_skill returns an error for any other file. Additional frontmatter settings do not install tools, dependencies, or scripts. The card warns that everyone who can use the chat can pick the skill. A saved skill is listed in the conversation's write history, so the assistant can undo it. The assistant can't edit an existing skill; change it on the Skills page. Creating a skill does not apply it to the current chat; reload the page to refresh the skills menu, then select it when you want to use it.
Export skill, on a skill's own page, goes the other way: it downloads that skill as a .md file in exactly this shape, ready to import into another app or keep in a repository.
Ejecting instructions (see Replace the shipped prompts) also gives you app/prompts/avo/ai/chat_agent/skills.txt.erb, the partial that renders the bodies into the system prompt. It receives one local:
| Local | Shape | Present when |
|---|---|---|
skills | Array of Avo::Ai::Skill | The chat has at least one skill attached, deduplicated and in first-attached order |
Connect other tools with MCP
Connect a remote MCP server from the chat, and the assistant can use that server's tools alongside Avo's own in the same turn, with the record you started the chat from as context. Every call it makes to the server waits for your approval on a card.
Connections are off until your app turns them on and decides who may connect a server. See Turn on MCP connections.
Type /mcp in the composer to open the Connections panel. On its own, /mcp lists the connections you can use, with each one's status and tools. With an address, /mcp https://mcp.linear.app/mcp starts connecting that server. /mcp is also a row in the / menu, next to your skills.
/mcp never reaches the model. Avo answers it before anything is stored: no message is added to the conversation, no chat is created when you type it into a new-chat composer, and the assistant isn't told. The assistant has no tool that connects, shares, or disconnects a server, approves a call, or changes a tool's setting, and it can't read or change connection records. People do all of that with clicks.
Connect a server
Give the panel the server's address and click Connect. The address must start with https://. Avo refuses anything else before it sends a request. It then asks the server what it needs:
| The server needs | What happens |
|---|---|
| Nothing | It connects right away |
| A sign-in | Continue to sign in takes you to the provider's consent screen and back to the chat you started from. The link lasts ten minutes |
| An access token | A masked Access token field. Paste a token the provider gave you and click Connect |
A server that offers a sign-in Avo can't use, for example one that needs a client registered with it ahead of time, gets the token field instead, with the reason.
Nothing is saved until the server accepts the connection. A rejected token, a sign-in that fails or that you abandon, or a server that doesn't answer within 15 seconds leaves no connection behind. When it works, the panel says so, the chat you connected from gets a line naming the server and how many tools it offers, and the assistant can use them from your next message.
You have one connection per server address. Typing /mcp with the address of a server you already connected points you to Reconnect instead of adding a second one.
People who can't connect servers still see the connections they can use, and a line telling them to ask an admin.
Share a connection
A new connection is yours alone. It shows up only in your chats and your /mcp list. If your app lets you share, Share with everyone in the panel makes it usable in everyone's chats, and Make private takes it back. The connection's page on the Connectors resource has the same choice.
A shared connection sends every call with your credential, so on the server's side a colleague's call looks like yours. Each card names whose connection the call goes through, and the audit log records the colleague whose chat made the call. Making a connection private again takes back the always-allows other people gave its tools.
Only the owner can share a connection, make it private, or reconnect it.
Approve a call
When the assistant calls a remote tool, the turn stops on a card showing the server and its host, the tool, whose connection the call goes through ("Your connection", or "Maria's connection" for a shared one), and the exact arguments that will leave your app. Nothing is sent until you click one of three buttons:
| Button | What it does |
|---|---|
| Approve once | Sends this call. The result comes back and the assistant carries on |
| Always allow | Sends this call, and skips the card for this tool from now on |
| Decline | Sends nothing. The assistant is told you declined and carries on with what it can still do |
A remote card only takes a click
Typing "yes" or "do it" confirms Avo's own cards but never a remote one. What a server returns, and what the assistant reads in a record or a document, is text someone else wrote, and it could contain those words. A message you send while a remote card is open settles the card as Not sent, and the assistant answers your message instead.
When one reply makes several calls, each gets its own card, and the assistant carries on once you've answered all of them.
Always allow is yours, for one tool. It doesn't cover other people, other tools, or other connections. It stops applying when the connection's owner sets the tool to Always ask, when the server changes the tool's name, description, or arguments, and when the connection is reconnected. The next call then shows a card again.
Ten in a row, then a card. At most ten always-allowed calls run in a row before a card appears again. The count starts over when you send a message or answer a card.
A call that may have gone through isn't repeated behind your back. A remote call ends after 30 seconds without an answer, or after a minute in all. If the server doesn't answer in time, or the connection drops after the call was sent, the assistant is told the call may have happened and not to repeat it, and its card, if it had one, reads Outcome unknown. The next call to that tool shows a card even if you always-allowed it, so check the other system before you approve it.
A card left for more than an hour can't be approved anymore and reads Expired. If a server asks for more input in the middle of a call, the assistant tells you what it asked, and the call counts as not done.
Manage a connection
Each connection has a page on the Connectors resource, once your app adds it to the menu. It shows the owner, who can use the connection, its status, and its tools. Everyone who can use a shared connection can read its page. The credential is never shown, and neither is any part of the address after a ?.
The owner, or whoever else your app lets manage the connection, sets each tool:
| Setting | Means |
|---|---|
| On | The assistant can call it. Each call shows a card unless the user always-allowed the tool |
| Always ask | Every call shows a card, and Always allow isn't offered. Existing always-allows stop applying |
| Off | The assistant isn't offered the tool |
Tools a server adds later arrive On. Switch off the tools nobody should use from a chat, especially on a shared connection. A change applies from the next call, even in a reply that's already running: always-allows stop at once, and a tool switched Off is no longer sent.
They also get three actions on the connection's page:
- Refresh tools reads the server's tool list now. That list is what the assistant searches: a new tool arrives switched on, a tool the server no longer lists is removed unless it's set to Always ask or Off (a list with no tools at all removes nothing), and a tool the server changed shows a card before its next call. Chats also read the list just before each call, so a change on the server is never missed for long.
- Revoke always-allows takes back every always-allow anyone gave the connection's tools. The next call to each one shows a card.
- Disconnect removes the connection, its credential, its tools, and the always-allows on them. Its tools leave every chat from the next message, and past messages that used them stay readable.
The /mcp panel has Reconnect and Disconnect too.
When a connection stops working
A connection that fails never breaks the chat. Avo's own tools keep working, and when the assistant calls a tool on a server it can't reach, nothing is sent and it tells you which connection failed and that it can be reconnected with /mcp.
| What happened | What you see |
|---|---|
| The server didn't answer in time, or couldn't be reached | That call isn't sent, and the assistant can try it again once the server answers |
| The server rejected the credential, or it can't be read | The connection reads Needs reconnecting in /mcp |
Only the owner can reconnect. Reconnect in the /mcp panel signs in again, takes a new token, or simply asks again for a server that needs neither. Other people see who to ask. Reconnecting takes back every always-allow on the connection, since the new credential may belong to a different account on the server.
Dictate a message
The microphone in every composer — the bar, the new-chat page, and open conversations — transcribes speech into the message box: click to start, click to stop. Pauses don't end the session, and the text lands on top of whatever draft is already there, so you can type half a message and speak the rest.
An open session ends the moment you stop needing it: sending the message stops the mic, and so does minimizing the window or switching to another chat in the dock, so nothing keeps listening behind a window you've left.
It dictates in your admin's language: the recognizer follows the page's lang attribute, falling back to the browser's own language setting.
Browser support, and where the audio goes
Dictation is the browser's built-in Web Speech API, not something the assistant does. There's no API key to set, and neither Avo nor your LLM provider ever sees the audio — they only get the finished text, and only when you send the message. Who does see it depends entirely on the browser, and they don't answer alike:
| Browser | Support | Where recognition runs |
|---|---|---|
| Safari | 14.1+ macOS, 14.5+ iOS | Apple's speech stack — on device where the language and hardware allow it, Apple's servers otherwise. Safari asks the first time, and the prompt says as much. |
| Chrome, Edge | Yes | Google's speech service: the audio is uploaded, so dictation needs a connection. Chrome 139 added an opt-in on-device mode, which Avo doesn't request. |
| Firefox | No | Nowhere — unimplemented, behind a disabled dom.webspeech.recognition.enable flag. |
The microphone only renders where the API exists, so Firefox users get a composer with no mic rather than a button that does nothing.
WARNING
In Chrome and Edge, dictating means uploading admin-panel audio to Google. If that doesn't fit your compliance story, tell your admins to dictate in Safari — there's no gem setting that changes it, because the browser owns the audio path.
While the assistant is replying
Your message lands on the transcript the moment you send it, with a Thinking indicator underneath. The browser puts it there as the request leaves, and the saved message replaces that copy when it arrives, so the turn is on screen for the whole round trip and never blinks out for the second or two the queue takes.
Starting a fresh conversation does the same with the whole opening turn: your prompt and the Thinking indicator take the place of the greeting and its suggestions, and the real conversation replaces them once it's ready, so there's no empty panel in between. A second Enter while that's happening doesn't start a second chat.
If the send fails, the prompt comes back out of the transcript, the greeting returns, and what you typed is back in the composer to retry.
When answering takes real work — a lookup, an inspection, a write — the assistant leaves short progress hints while it works: Inspecting the schema, Checking today's signups. They render small and muted, alongside the reasoning trace, so they read as status rather than replies — and they name the goal in your terms, never the tool it reaches for. It's what you read while the work happens instead of watching an empty panel.
When the answer lands, the worked trail folds up: everything between your question and the reply — the reasoning, the hints — collapses into a single Worked for 12 seconds row above the answer, so a settled conversation reads question, one quiet row, answer. Open the row to see how the assistant got there; viewers with the :tools debug level find the tool calls in there too.
You can keep typing while it works. A message sent before the current answer lands doesn't interrupt it — it waits in a short list above the composer, in the order you sent it, and goes out on its own the moment the assistant finishes. One turn at a time, so two replies never race each other in the same conversation.
While a message waits you can move it to the front of the line or drop it, which is the point of showing you the wait rather than hiding it. The list belongs to the page you typed on: reloading clears it, the same way it clears anything else you'd typed but not sent.
The indicator is read from the conversation itself rather than from what your browser happened to witness. Reload mid-reply, or open the chat in full page while it's working, and the indicator is still there waiting on the same reply — the answer streams in wherever you're watching from when it lands. It clears when the assistant's reply arrives, when a card or a question hands the turn back to you, or when the run fails and says so.
When a reply fails
A run can fail: the provider is down or rate-limiting, an API key is missing, the conversation outgrew the model's context window, or something in the app raised. When that happens the conversation gets an error row where the answer would have been, the Thinking indicator clears, and the message you sent stays in the transcript, unanswered.
The row carries one sentence, chosen by what went wrong:
| What happened | What the row says | Try again |
|---|---|---|
| Rate limit, overload, a 5xx, a timeout, or the network | Names the provider and says it is busy or unreachable | Yes |
| The provider is not configured | Names the provider; someone with access to the AI settings needs to finish its setup | Yes |
| The provider rejected the app's credentials | Names the provider; someone with access to the AI settings needs to check the API key | Yes |
| The provider reports a billing or quota problem | Names the provider; someone with access to the provider account needs to look | Yes |
| The app cannot use the requested model or feature | Names the provider; someone with access to the provider account needs to look | Yes |
| The chat's model isn't in the registry | Names the provider; pick another model or refresh the models | Yes |
| The conversation is longer than the model's context window | Start a new chat | No |
| The provider called the request invalid, or refused an attachment type | Names the provider; start a new chat, or resend without the attachment | No |
| The chat was turned off for this user while a reply was queued | Says the assistant is turned off for their account | No |
| Anything else | Something went wrong | Yes |
Try again starts a new run for the message that went unanswered. It adds nothing to the transcript. The button only shows on the last row of the conversation, and only when running the same conversation again can work: a rejected API key gets one because someone can fix the key, a conversation that is too long doesn't. Sending a new message works too. The assistant then answers both.
Error rows are never sent to the model.
When the worker dies mid-reply
A worker that is killed mid-run, by a deploy or an out-of-memory kill, gets no chance to write an error row. The conversation covers that case itself: once nothing has been added to it for 10 minutes and no run holds the chat, it shows The assistant stopped before it finished answering with the same Try again. A page that was open the whole time shows it without a reload.
Where the failure is reported
A failed run is handled inside the job, so it does not raise. Your queue won't retry it on its own schedule (which would post the same error row again each time), and it won't appear in the queue's failed or dead set. The exception goes to the Rails error reporter instead, marked handled: true, with the chat's id as context. Sentry, Honeybadger, AppSignal, and Bugsnag subscribe to it out of the box. To subscribe yourself:
# config/initializers/error_subscriber.rb
class AiFailureSubscriber
  def report(error, handled:, severity:, context:, source: nil)
    return unless context[:chat_id]

    Rails.logger.error("AI chat #{context[:chat_id]} failed: #{error.class}")
  end
end

Rails.error.subscribe(AiFailureSubscriber.new)
The log line avo-ai writes itself ([Avo::Ai] Chat 42 run failed: RubyLLM::RateLimitError) names the exception's class and nothing else, because a message can carry SQL values or an internal URL.
Who sees what went wrong
Everyone sees the sentence. The exception itself, its class and the provider's message, renders under it only for a viewer at the :tools debug level; at :off it never reaches the page. The row stores the exception's class until the chat is deleted. It stores the message only when the error came from the provider. For anything raised by the app it keeps the class alone, and your error tracker has the rest.
Upgrading an existing install
Error rows keep their kind in a new avo_ai_messages.error_details column. Re-run the installer to get its migration, then migrate:
bin/rails generate avo:ai install
bin/rails db:migrate
The installer only writes what your app is missing. Until the column exists error rows still appear and still clear the indicator, but they carry no Try again.
The same run adds avo_ai_write_logs.pending_write_id, which ties a batch update's records together so undo treats the batch as one change. Until it exists, a batch is listed and undone record by record.
When each message was sent
A divider marks the start of every day in the transcript: Today, Yesterday, the weekday name for anything else inside the past week, then a date — Jul 26, and Sep 24, 2025 once it isn't this year — each followed by the clock time of that day's first message.
Day and month names come from your locale, and the Today and Yesterday words are locale keys (avo.ai.messages.today and avo.ai.messages.yesterday), so a translated admin panel gets translated dividers.
Dividers are worked out when the page renders, not as each message arrives. Leave a conversation open across midnight and it picks up the new day's divider on the next full load.
Copy a message
Hover any message and a copy button appears beneath it. It copies the raw text the assistant produced — the markdown it wrote, not the rendered HTML — so pasting it into an issue or an editor keeps the formatting.
Rate a reply
Every assistant reply has a thumbs up and a thumbs down beside its copy button. A click opens a modal; nothing is recorded until you press Send feedback, or Cmd+Return (Ctrl+Return on Windows and Linux) while typing the comment. Both fields in it are optional, so sending an empty modal still records the vote. Closing the modal (Cancel, the close button, Esc, or a click outside it) records nothing.
- Thumbs down asks "What went wrong?" with an optional reason picked from a dropdown: Wrong or inaccurate, Didn't follow instructions, Wrong records or data, Took an action I didn't want, Too slow or verbose, or Other. A comment box sits under it.
- Thumbs up asks "What did you like about this response?" and takes a comment.
Each send leaves a new feedback. Clicking a thumb again, either one, opens an empty modal for another feedback instead of the one you sent before, so you can rate the same reply more than once. The thumb of your last sent vote stays highlighted. A feedback can't be edited, removed, or switched to the other vote once it's sent.
Only the chat's owner can rate its replies, the same way only the owner can read the chat. Deleting a chat deletes its feedback.
Review feedback
Feedback lands in the Feedback resource. Add it to the menu beside the others:
# config/initializers/avo.rb
section "AI", icon: "heroicons/outline/sparkles" do
  resource "avo_ai/chats"
  resource "avo_ai/messages"
  resource "avo_ai/models"
  resource "avo_ai/skills"
  resource "avo_ai/feedbacks"
end
Each record shows the vote, the reason, the comment, the prompt the user sent, the reply they rated, the model that produced that reply, the author, and a link to the chat. Filter the index by vote, reason, status, or model.
You triage a record with two fields of your own: Status (Open, In progress, or Resolved) and Admin note. Those are the only fields you can edit. The user's vote, reason, and comment are read-only, in the resource and for the user, so a triaged record never changes under you.
Choose who can review feedback
Feedback contains other people's conversations, so the gem ships Avo::Ai::FeedbackPolicy closed: nobody sees any feedback until you say who reviews it. Define your own Avo::Ai::FeedbackPolicy and open index?, show?, edit?, and update? for your reviewers. Your class wins over the gem's copy:
# app/policies/avo/ai/feedback_policy.rb
class Avo::Ai::FeedbackPolicy
  attr_reader :user, :record

  def initialize(user, record)
    @user = user
    @record = record
  end

  def index? = user.admin?
  def show? = user.admin?
  def edit? = user.admin?
  def update? = user.admin?
  def search? = user.admin?
  def act_on? = user.admin?
  # Feedback is written from the chat and deleted with its chat.
  def new? = false
  def create? = false
  def destroy? = false

  class Scope
    def initialize(user, scope)
      @user = user
      @scope = scope
    end

    def resolve
      @scope.all
    end
  end
end
Keep new?, create?, and destroy? closed. There is nothing to create from the admin side.
INFO
The resource checks this policy itself, so it stays closed without avo-authorization. With the gem's policy in place the index is empty and opening a record fails as not found.
Upgrading an existing install
Feedback is stored in a new avo_ai_feedbacks table. Re-run the installer to get its migration, then migrate:
bin/rails generate avo:ai install
bin/rails db:migrate
The installer only writes what your app is missing.
Turn feedback off
Feedback is on by default. Turn it off in the initializer:
# config/initializers/avo.rb
config.ai.feedback_enabled = false
This hides the thumbs under every reply and refuses new votes. Feedback already collected stays reviewable in the Feedback resource.
Notify reviewers of new feedback
Requires avo-notifications. Point feedback_notification_recipients at whoever should hear about new feedback:
# config/initializers/avo.rb
config.ai.feedback_notification_recipients = -> { User.where(role: "admin") }
It's a zero-argument lambda, and feedback is available inside it. Return a user, an Array of users, or a relation. It runs in a background job, never in the request that sends the feedback, so a slow lookup never delays it. Leave it unset (the default) and nobody is notified.
Narrow which feedback notifies with feedback_notification_events:
# config/initializers/avo.rb
config.ai.feedback_notification_events = [:downvotes, :with_description]| Value | Notifies on |
|---|---|
:all | Every vote. The default. |
:downvotes | Thumbs down. |
:upvotes | Thumbs up. |
:with_description | Any vote that carries a comment. |
The events are checked once, when the user sends the feedback, and a feedback notifies at most once. The vote, reason, and comment arrive together, so the notification carries the reason in its title and the comment in its body. Each send is a new feedback, so a second one on the same reply can notify again. An unknown event raises at boot.
The notification names the vote and its reason, carries the comment as its body, and links to the feedback record in Avo. A thumbs down sends at :warning level; a thumbs up sends at :info level.
INFO
A notification failure is logged and never affects the vote. The vote is already saved by the time the notification runs.
Choose which models people can use
By default a chat runs on the model you configured in config/initializers/ruby_llm.rb, and there is no model picker — the RubyLLM registry is thousands of models long, which is not a dropdown.
Give your Avo::Ai::ChatPolicy an #available_models method to curate a shortlist. Every composer — the bar, the new-chat page, and open conversations — then shows a picker with exactly those models:
# app/policies/avo/ai/chat_policy.rb
class Avo::Ai::ChatPolicy < ApplicationPolicy
  def use? = user.present?

  def available_models
    return nil if user.admin? # every model in the registry

    [
      {model: "claude-haiku-4-5", provider: :anthropic},
      {model: "claude-sonnet-5", provider: :anthropic},
      {model: "gpt-4o-mini", provider: :openai},
      {model: "claude-opus-4-8", provider: :anthropic},
      {model: "gemini-2.5-flash", provider: :gemini}
    ]
  end
end
Why the namespace is Avo::Ai, not Avo::AI
The constant is spelled Avo::Ai on purpose — it's what Rails derives from the avo/ai path on its own. An acronym constant never comes for free: Zeitwerk camelizes ai to Ai, so every app defining its own classes in the namespace — exactly what you're doing here with app/policies/avo/ai/chat_policy.rb — would need an inflection in its config/initializers/inflections.rb to make the constant resolve. With standard camelization there is nothing to configure.
Each entry names a RubyLLM registry model, and provider: says which provider serves it. Browse what your app knows about through the Models resource in the sidebar, or in the console with RubyLLM.models.chat_models.all.map { |m| [m.id, m.provider] }.
A bare id works too — "gpt-4o-mini" instead of the pair — and is the shorter thing to write when the id is unambiguous. Naming the provider is worth the extra keys anyway: several ids are served by more than one provider, and pinning is how you say which one your app talks to.
| Return value | What happens |
|---|---|
nil, or no method at all | Every model in the registry, no picker, chats use the configured default. |
| Two or more entries | The picker offers exactly those, in the order you listed them. |
| One entry | No picker — there's no choice to make — and every chat runs on that model. |
| A list containing an unknown entry | That entry is dropped; the rest of the list stands. The log names it. |
| A list of nothing but unknown entries | No model to start a chat on, and chat creation is refused. |
Your list is taken exactly. Three things follow from that, and they're the ones worth knowing:
- Order is yours. The picker reads back in the order you wrote, not alphabetically, and the first entry is what a new chat starts on. Put the model you want people reaching for at the top. There's no "the configured default" entry in the picker — it would only ever name a model already in your list.
- Ids must match character for character. No aliases, no near matches.
claude-sonnet-4-8doesn't becomeclaude-sonnet-4-6because you meant it to. - An unknown entry is simply absent. It doesn't widen the catalog back to the whole registry — the log names it (
ChatPolicy#available_models lists unknown chat models: …) and the rest of your list stands. A list of nothing but typos leaves no model to chat on, and chat creation is refused rather than quietly falling back to one you never granted.
The list is enforced on every chat create and every message, not just in the picker — the picker is UI, the server re-checks. A user can't start a chat on, or switch a chat onto, a model you withheld by crafting the request themselves.
Pinning the provider
provider: is what makes the pair worth writing. Several ids are served by more than one provider — gemini-2.5-flash comes through both Gemini and VertexAI, and much of Anthropic's catalog is also on Bedrock and VertexAI — and the key says which one your app talks to.
Leave it off and the id still resolves, just not to a provider you chose: RubyLLM picks by its own preference order (OpenAI, Anthropic, Gemini, VertexAI, Bedrock, OpenRouter, …), exactly as if you had handed the bare id to RubyLLM.chat.
def available_models
  [
    "gpt-4o-mini", # whichever provider RubyLLM prefers for this id
    {model: "gemini-2.5-flash", provider: :vertexai} # VertexAI's, not Gemini's
  ]
end
Provider is its own key rather than part of the string — the same shape RubyLLM uses everywhere (RubyLLM.chat(model:, provider:)), and the only workable one here, since real model ids already contain both / (OpenRouter) and @ (VertexAI).
Each id appears once in the picker either way: pinned, it's the provider you named; unpinned, it's the one RubyLLM prefers. Both the chat and each of its messages store the provider alongside the model, so the transcript says where every answer came from.
INFO
A pinned pair whose provider doesn't carry that model is dropped like any other unknown entry, and the log names both halves — model-id (provider).
WARNING
Pin only a provider you have configured. RubyLLM validates the provider's credentials when the chat is created, so pinning provider: :vertexai without VertexAI keys in config/initializers/ruby_llm.rb raises RubyLLM::ConfigurationError on the first chat rather than at boot.
Switching model mid-conversation
The picker stays in the composer once the chat exists, so a conversation can change models partway through: pick another model and send.
The switch takes effect from that message on. The transcript so far is replayed to the new model — nothing is lost, and the new model answers with the whole conversation in view — and each message records which model wrote it.
The picker is disabled while the assistant is responding; the model is yours to change on your turn.
A chat keeps running on its model even if you later drop that model from #available_models. Its own picker still lists it — otherwise the dropdown would misreport what the next message runs on — and re-picking it is a no-op, so the conversation is never stranded. But nobody can switch a chat onto a model you've withdrawn.
Choose who can manage skills
Add the AI Skills resource to the menu beside the others:
# config/initializers/avo.rb
section "AI", icon: "heroicons/outline/sparkles" do
  resource "avo_ai/chats"
  resource "avo_ai/messages"
  resource "avo_ai/models"
  resource "avo_ai/skills"
end
By default, anyone who can use the chat can list, pick, create, edit, and destroy skills — authoring and using a skill share one policy surface, the same way choosing a model is one surface for every chat user.
Define your own Avo::Ai::SkillPolicy to narrow that. Your class wins over the gem's copy, and — like the gem's — it's a plain class rather than one that inherits your app's ApplicationPolicy, so it means the same thing no matter what your own base policy does:
# app/policies/avo/ai/skill_policy.rb
class Avo::Ai::SkillPolicy
  attr_reader :user, :record

  def initialize(user, record)
    @user = user
    @record = record
  end

  def index? = true
  def show? = true
  def new? = user.admin?
  def create? = user.admin?
  def edit? = user.admin?
  def update? = user.admin?
  def destroy? = user.admin?
  # Authorized separately from CRUD — without `search?` the resource's search box goes dark.
  # The composer's `/` menu reads `Scope#resolve` below, not `search?`.
  def search? = true
  def act_on? = true

  class Scope
    def initialize(user, scope)
      @user = user
      @scope = scope
    end

    def resolve
      @scope.all
    end
  end
end
Narrowing Scope#resolve reaches past the resource's own index: a skill the scope excludes also drops out of the composer's / menu, and out of any chat that already referenced it — the same way a deleted skill does (see Attach a skill with a message).
Turn on MCP connections
MCP connections are off by default. While they're off, nobody sees any of it: no /mcp, no connection pages, and no remote tools in any chat. Turning them on takes encryption keys, the installer's tables, one setting, and a policy that says who may connect.
Set it up
Connections store each server's credential with Active Record encryption. If your app has no encryption keys yet, generate them and add them to your credentials:
bin/rails db:encryption:initA new install already has the tables. An app that installed avo-ai earlier runs the installer again, which writes only the migrations it's missing: avo-ai's connection tables and RubyLLM's MCP credentials table.
bin/rails generate avo:ai install
bin/rails db:migrate
Turn the setting on:
# config/initializers/avo.rb
config.ai.connectors_enabled = true
Add the Connectors resource to the menu beside the others:
# config/initializers/avo.rb
section "AI", icon: "heroicons/outline/sparkles" do
  resource "avo_ai/chats"
  resource "avo_ai/messages"
  resource "avo_ai/models"
  resource "avo_ai/skills"
  resource "avo_ai/connectors"
end
Migrate before you turn the setting on, since every chat reads the connection tables while it's on. If the encryption keys or RubyLLM's credentials table are missing, connecting a server tells the user the app isn't set up yet instead of failing.
When someone signs in to a server, Avo registers itself with that provider on the spot, once per connection. The consent screen shows your Avo app_name.
Choose who can connect and share
The setting alone lets nobody connect. Avo::Ai::ConnectorPolicy ships with create? (connecting a server) and share? (sharing one with everyone) both closed. Define your own class to open them. It wins over the gem's copy and, like the gem's, it's a plain class rather than one that inherits your ApplicationPolicy:
# app/policies/avo/ai/connector_policy.rb
class Avo::Ai::ConnectorPolicy
  attr_reader :user, :record

  def initialize(user, record)
    @user = user
    @record = record
  end

  # Connecting a server.
  def create?
    enabled? && admin?
  end

  # Sharing a connection with everyone.
  def share?
    enabled? && admin?
  end

  def index?
    enabled?
  end

  def show?
    enabled?
  end

  def new?
    create?
  end

  def edit?
    update?
  end

  # Tool settings, Refresh tools, and Revoke always-allows.
  def update?
    enabled? && owner?
  end

  # Disconnecting.
  def destroy?
    enabled? && owner?
  end

  def search?
    enabled?
  end

  def act_on?
    enabled?
  end

  # Tool rows come from the server, so the tools table on a connection's page
  # offers no attach, detach, or create.
  def attach_connector_tools? = false

  def detach_connector_tools? = false

  def create_connector_tools? = false

  private

  def enabled?
    Avo.configuration.ai.connectors_enabled
  end

  def admin?
    !!user&.admin?
  end

  def owner?
    record.respond_to?(:owned_by?) && record.owned_by?(user)
  end

  class Scope
    def initialize(user, scope)
      @user = user
      @scope = scope
    end

    # The user's own connections, plus shared ones whose owner may still connect.
    def resolve
      return @scope.none unless Avo.configuration.ai.connectors_enabled

      mine = @scope.where(user_type: @user.class.name, user_id: @user.id)
      usable = @scope.where(audience: "everyone").includes(:user).select do |connector|
        connector.user && Avo::Ai::ConnectorPolicy.new(connector.user, connector).create?
      end

      mine.or(@scope.where(id: usable.map(&:id)))
    end
  end
end
Keep the enabled? check in every method and the early return in Scope#resolve. The gem's policy answers no to everything while config.ai.connectors_enabled is off, and your class replaces it. The Connectors pages and the servers a chat can call both go through this policy, so without the check they keep working with the setting off.
Scope#resolve decides what each person can use, in the chat and on the Connectors pages alike. Checking the owner's create? for shared connections is what stops a shared connection for everyone when its owner loses the permission.
Answer from user, never from a current-user global
Scope#resolve asks create? about the owner of somebody else's connection. A policy that reads Current.user answers about the wrong person and keeps sharing a connection whose owner should no longer have one.
Sharing, making a connection private, and reconnecting stay with the owner whatever the policy says: each one decides whose credential everyone's calls go out with. If you want someone else to manage every connection, return @scope.all from resolve for them and let update? and destroy? through. That widens the admin pages only: a chat still reaches just its user's own connections and the shared ones, so no one's assistant calls out on another person's private credential. A narrower scope does narrow the chat.
Record remote calls in the audit log
With Audit Logging installed, every remote call leaves one activity when it ends, whether or not it was sent. It's recorded against the connection, under the person whose chat made the call, with the chat as its origin. It names the connection, its host, the tool, whether the call was approved on a card or always-allowed, and how it ended. The arguments are left out: they're the part most likely to carry customer data, and more people read the audit log than the chat. The gem's Connectors resource turns this on with self.audit_logging, so keep that line if you replace the resource with your own.
Before you open it up
Weigh these before you grant create? and share?:
- Always-allowed calls send arguments nobody reviewed. Once someone always-allows a tool, the assistant sends whatever arguments it chooses, with no card, up to ten calls in a row. Set tools that change or send things to Always ask, especially on shared connections.
- Sharing puts a server's text in front of everyone's assistant. A server writes its own tool names and descriptions, and a shared connection puts them into the assistant's context in the chats of everyone it's shared with. The assistant treats them as data and every call still waits for a card, but a hostile or compromised server can still try to steer the conversation. Give
share?to people you'd trust to vet a server for the whole team. - HTTPS is the only network check. Avo refuses plain
http, follows no redirects, and verifies certificates, which keeps out cloud metadata endpoints and most internal services. An internal service with a publicly trusted certificate can still be reached from a connection address, so keepcreate?to people you'd trust with your network. - A remote action takes one more step. The assistant searches a connection's stored tools before it calls one. Until it does, nothing about the connections goes to your model provider beyond two tools and a line per connection in its instructions. A search returns at most five tools, with their arguments.
- Remote results go to your model provider. Like any tool result, what a server returns is sent to the provider and stored on the tool call. A result over 100 KB is cut short.
Turn the chat on or off per user
use? on your Avo::Ai::ChatPolicy decides whether a user can use the chat. Key it off a role, a plan, or a feature flag:
# app/policies/avo/ai/chat_policy.rb
class Avo::Ai::ChatPolicy < ApplicationPolicy
  def use? = user.admin? || user.support?

  # ...the rest of the policy
end
Its record is always the Avo::Ai::Chat class, so key it off user. The chat bar asks it on every panel page, so keep it cheap: read a column or a memoized flag. It also runs in background jobs, so don't read a tenant or other request state from it. If it raises, the chat reads as off for that user, and nothing is logged. A user it refuses:
- sees no chat bar, and Cmd+J / Ctrl+J opens nothing;
- is told they're not authorized on every chat page, and on every request behind them, sending a message included;
- gets no reply to a message still queued when you turned the chat off. The queued reply doesn't call the model. It posts an error row, The assistant is turned off for your account, so this message wasn't answered., with no Try again, and no title is generated for it. A reply already running finishes.
use? only decides whether they can use the chat. Beyond the chat's own controls, including the composer and the open-in-bar button on a chat's resource page, it doesn't hide anything: the Chats, Messages, Models, Skills, Feedback and Connectors menu entries and pages keep following their own policy methods, so a super admin can still review conversations there. To take an entry away, refuse index? for the same users.
If your menu links to the chats, hide the link for the same users with visible: -> { Avo::Ai::Chat.usable_by?(current_user) }.
use? needs an authorization client. With config.authorization_client = nil no policy runs, so nobody is blocked.
With avo-permissions as the client, no policy is asked, the shipped one included: a role needs a use? permission on Avo::Resources::AvoAi::Chat, or the chat is off for it. The permissions screen doesn't offer it yet, so add it from a console as the upgrade guide shows.
Your own ChatPolicy needs use?
The chat asks use? the way Avo asks any policy method, so a ChatPolicy of your own without it turns the chat off for every user. That is on purpose: a typo in a switch that guards access should refuse, not allow. If you already have a ChatPolicy, add def use? = user.present? when you upgrade to keep the chat on for everyone. The policy avo-ai ships, used when you have none, answers true for every signed-in user.
Who can see a chat
The chat UI only ever loads the signed-in user's own conversations, and the Chats and Messages admin resources list only theirs. Those resources still open any record by id, though, so close them with policies that scope to the owner:
# app/policies/avo/ai/chat_policy.rb
class Avo::Ai::ChatPolicy < ApplicationPolicy
  def use? = user.present?
  def index? = user.present?
  def show? = owner?
  def create? = user.present?
  def update? = owner?
  def destroy? = owner?

  private

  def owner? = user.present? && record.user == user

  class Scope < ApplicationPolicy::Scope
    def resolve = scope.where(user: user)
  end
end

# app/policies/avo/ai/message_policy.rb
class Avo::Ai::MessagePolicy < ApplicationPolicy
  def index? = user.present?
  def show? = owner?
  def create? = false
  def update? = owner?
  def destroy? = owner?

  private

  def owner? = user.present? && record.chat&.user == user

  class Scope < ApplicationPolicy::Scope
    def resolve = scope.where(chat: Avo::Ai::Chat.where(user: user))
  end
end
A chat or message outside the scope is a 404, admins included. create? is closed on messages because they are written by the chat; the admin form would let someone append to another person's conversation.
Who can delete a chat
Chats are owner-scoped already — nobody sees anyone else's — so by default a person can delete their own. Give your Avo::Ai::ChatPolicy a #destroy? method to take that away:
# app/policies/avo/ai/chat_policy.rb
class Avo::Ai::ChatPolicy < ApplicationPolicy
  def use? = user.present?

  def destroy?
    user.admin?
  end
end
Withheld, the delete entry disappears everywhere it appears: the chat bar's ⋯ menu, the chat page's ⋯ menu, and the rows on All chats — a button that would only 403 is worse than no button. The controller checks the same policy on the DELETE itself, so hiding the entries isn't what enforces it.
It's decided per chat, so a policy that allows deleting some and not others is honored: the bar reads the answer for whichever conversation is loaded, not once for the session.
No policy, or no #destroy? method, leaves deletion open: an app that never had a policy keeps the behavior it had before one existed. An error raised inside the policy fails closed, unlike debug levels — this one is destructive.
WARNING
Deletion is permanent, and it takes everything belonging to the conversation with it: the messages, the tool calls, any unconfirmed writes, and the audit log of the writes it executed. The records the assistant created or changed are untouched — it's the history of who asked for what that goes. If you need that history to outlive the chat, withhold #destroy? and archive instead.
Debug levels
How much of the assistant's internal work a viewer may see is an authorization decision, not a preference — the people chatting may be your customers, and the system prompt contains the rules that defend against jailbreaks.
There are two levels:
:off— the conversation: replies, record chips, confirmation buttons, the assistant's questions, the "Thinking…" indicator, and the collapsed trail with its reasoning trace and progress hints. The default.:tools— everything above plus the system prompt, the tool calls, the raw tool output, and the exception behind an error row.
The reasoning trace deliberately sits on the :off side of the line: it narrates the answer the viewer is already allowed to read, not the machinery. The system prompt and the raw tool traffic stay gated because they are the defenses.
The level is decided by your app's policy for Avo::Ai::Chat. It's never stored and never switchable from the chat UI:
# app/policies/avo/ai/chat_policy.rb
class Avo::Ai::ChatPolicy < ApplicationPolicy
  def use? = user.present?

  def debug_level
    user.admin? ? :tools : :off
  end
end
No policy, no #debug_level method, an unrecognized value, or any error inside the policy all fail closed to :off.
Viewers who get :tools also get a bug button — in the panel's title bar, and beside the ⋯ menu on the chat page — that hides those rows without leaving the conversation. It's a display preference, remembered per device and shared by both places. Nobody on :off sees the button, because none of those rows reach their browser to begin with.